

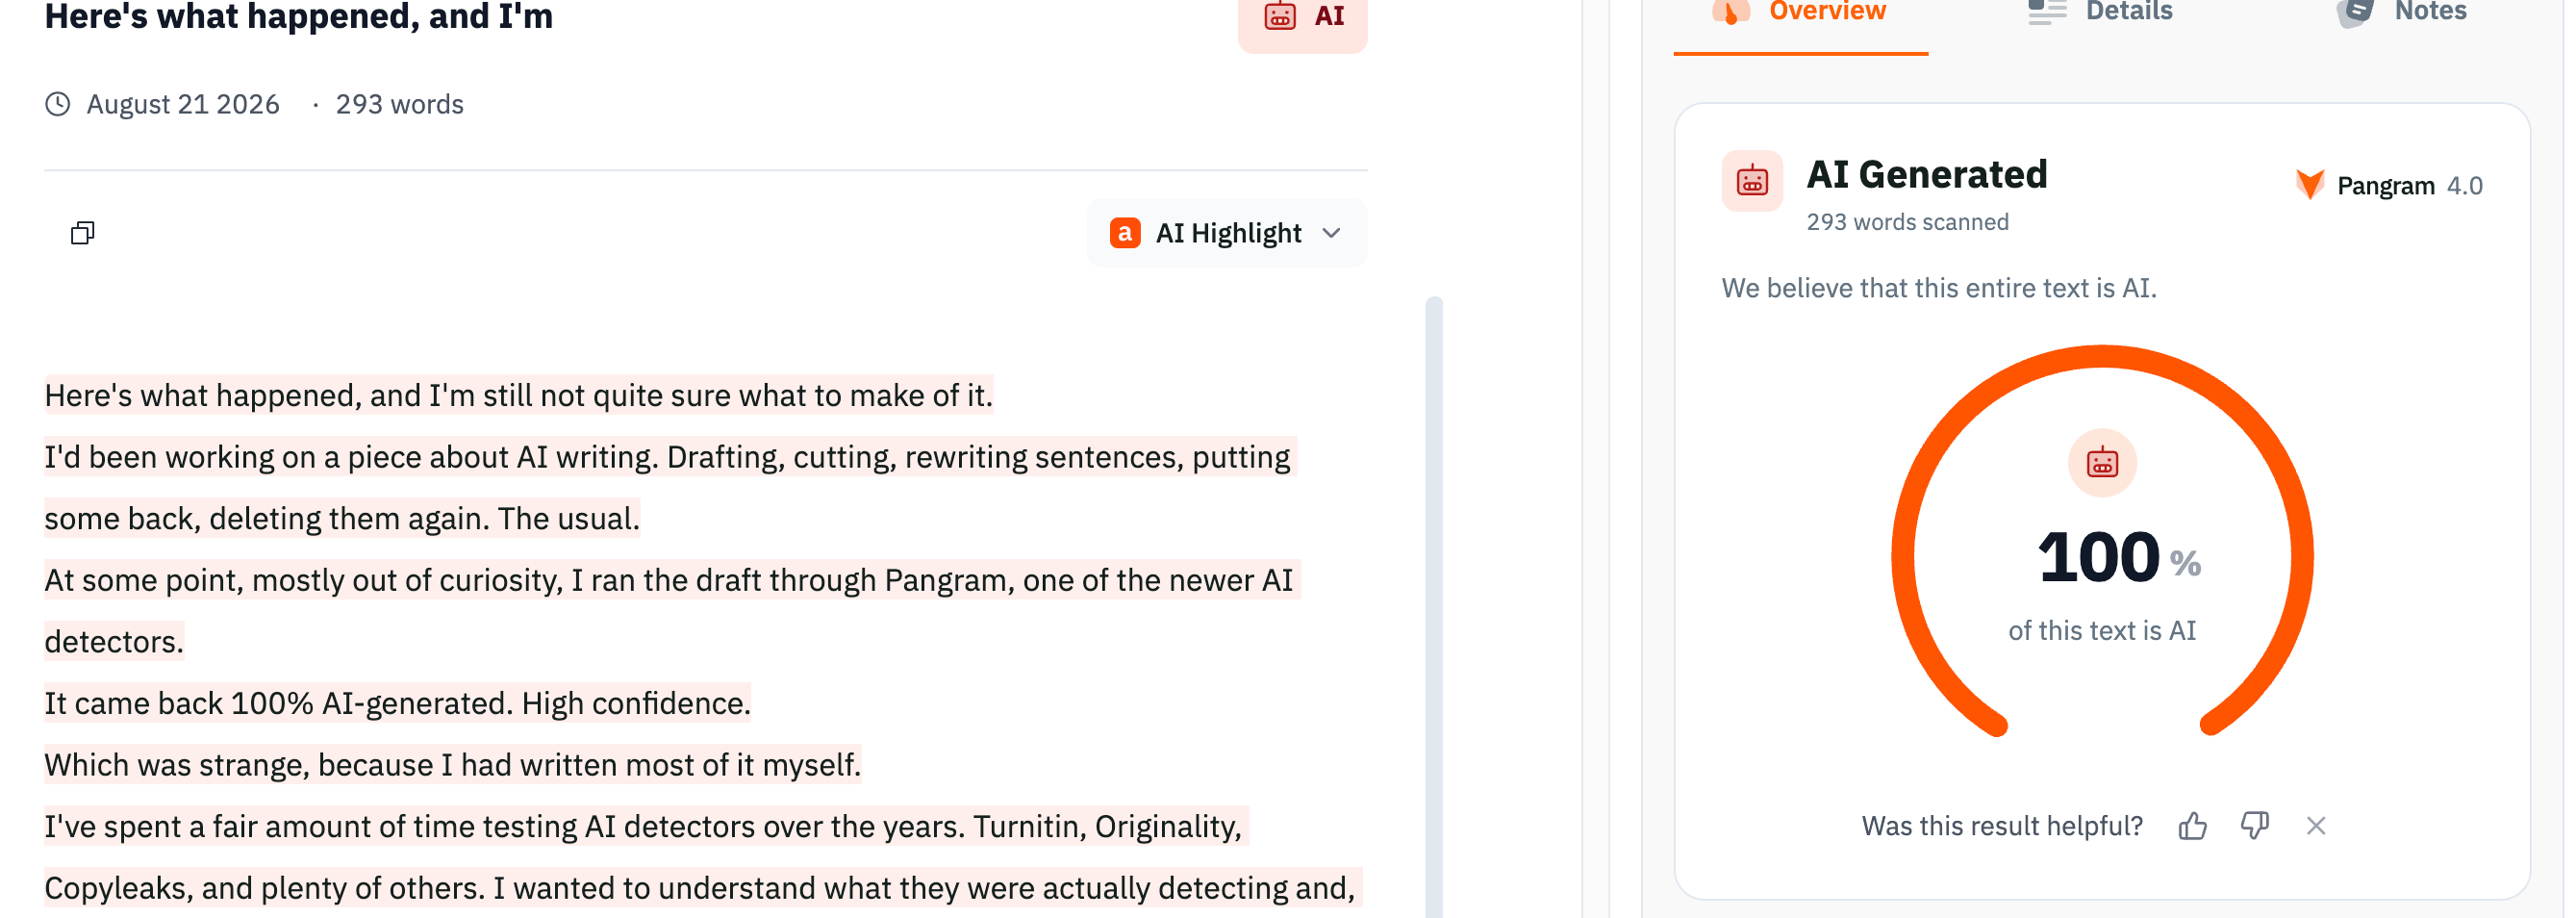
Here’s what happened, and I’m still not quite sure what to make of it.
I’d been working on a piece about AI writing. Drafting, cutting, rewriting sentences, putting some back, deleting them again. The usual.
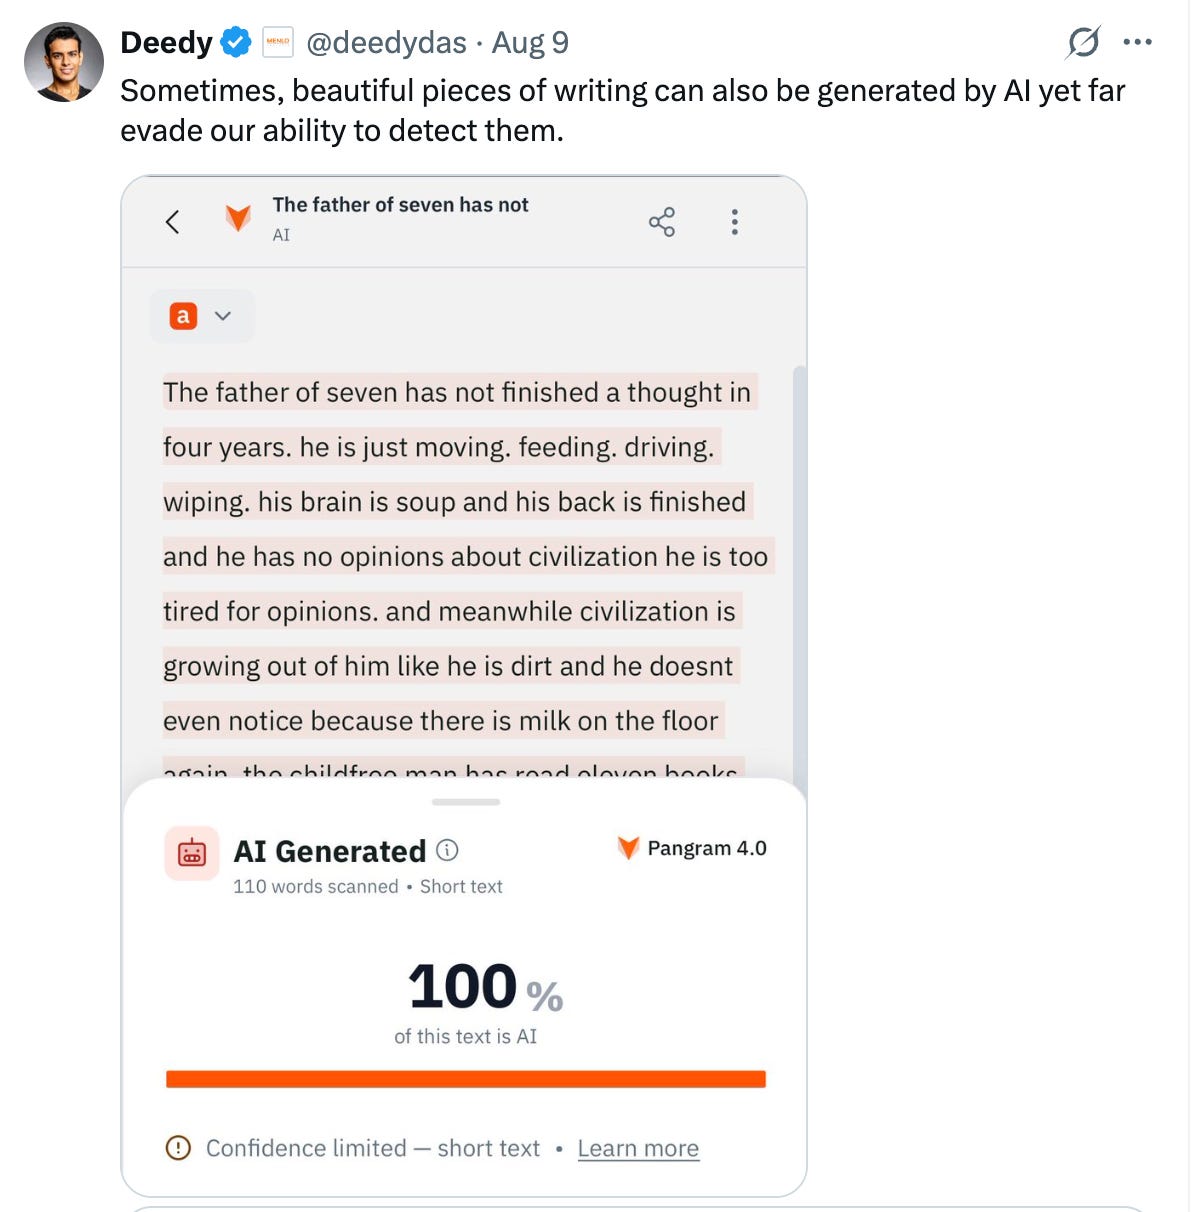
At some point, mostly out of curiosity, I ran the draft through Pangram, one of the newer AI detectors.
It came back 100% AI-generated. High confidence.
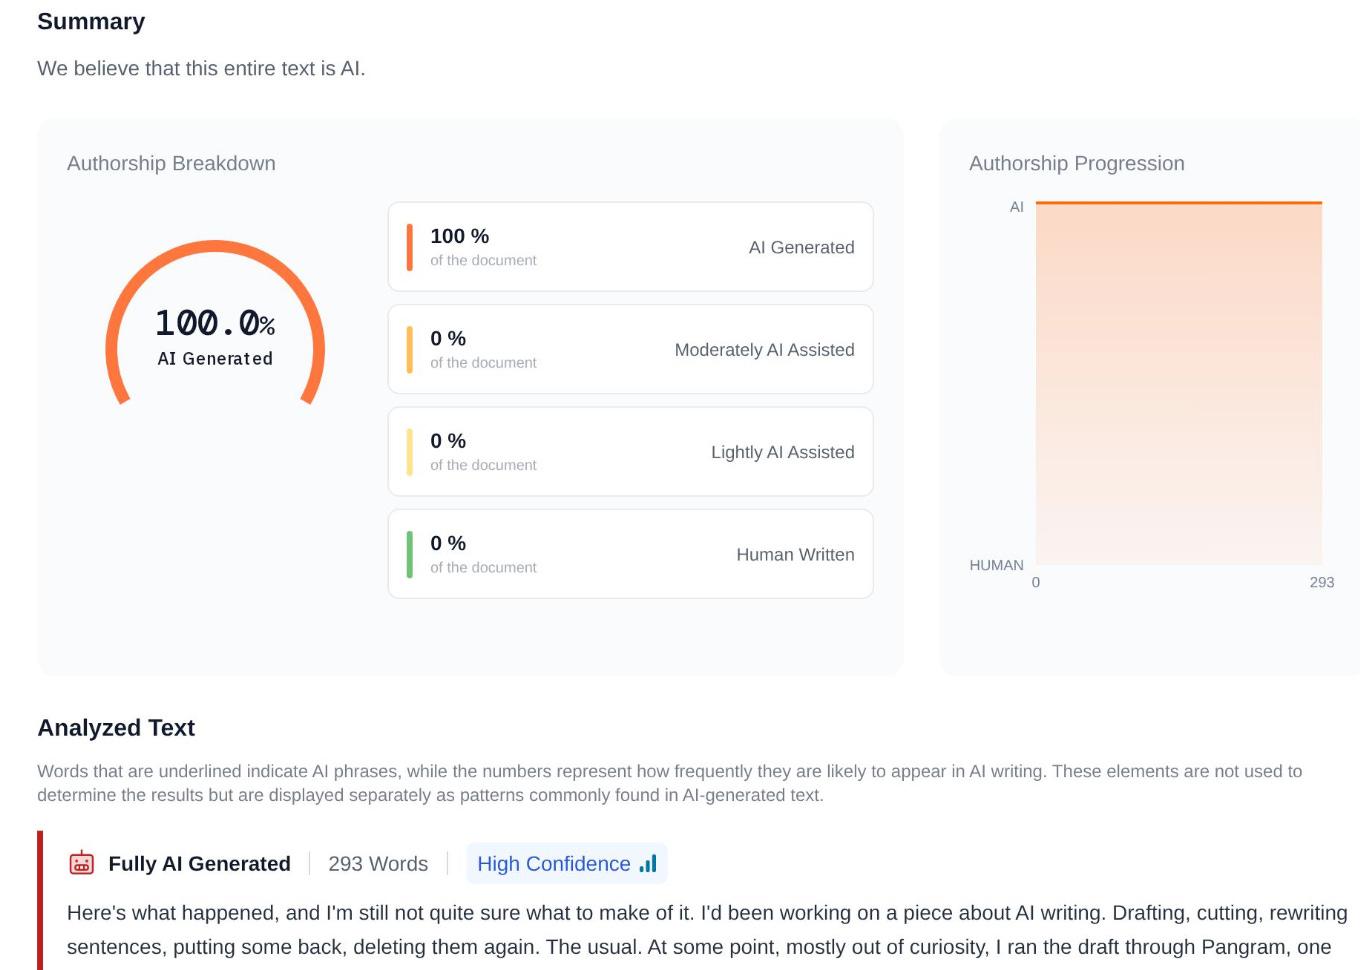
Which was strange, because I had written most of it myself.
I’ve spent a fair amount of time testing AI detectors over the years. Turnitin, Originality, Copyleaks, and plenty of others. I wanted to understand what they were actually detecting and, more importantly, whether I could trust the result.
I never could.
Yet the detector industry keeps growing. So does the market for “humanizers,” tools whose entire purpose is to make AI-generated writing look human enough to pass those detectors.
There’s a strange business cycle forming around all of this. One tool tells people their writing might be AI. Another promises to make it look human. The more worried people become about being labelled as AI-generated, the more useful both products appear.
And I’ve never been able to get past the basic contradiction.
If I use AI to generate something, then use another AI system to decide whether the first AI generated it, where does human judgment enter the process?
Of course, detectors aren’t doing nothing. There are patterns in machine-generated writing. Spend enough time comparing outputs and you start noticing repeated vocabulary, sentence structures, rhythms, and other statistical signals. Building systems that identify those patterns takes real technical work.
What I don’t understand is the confidence we place in the result.
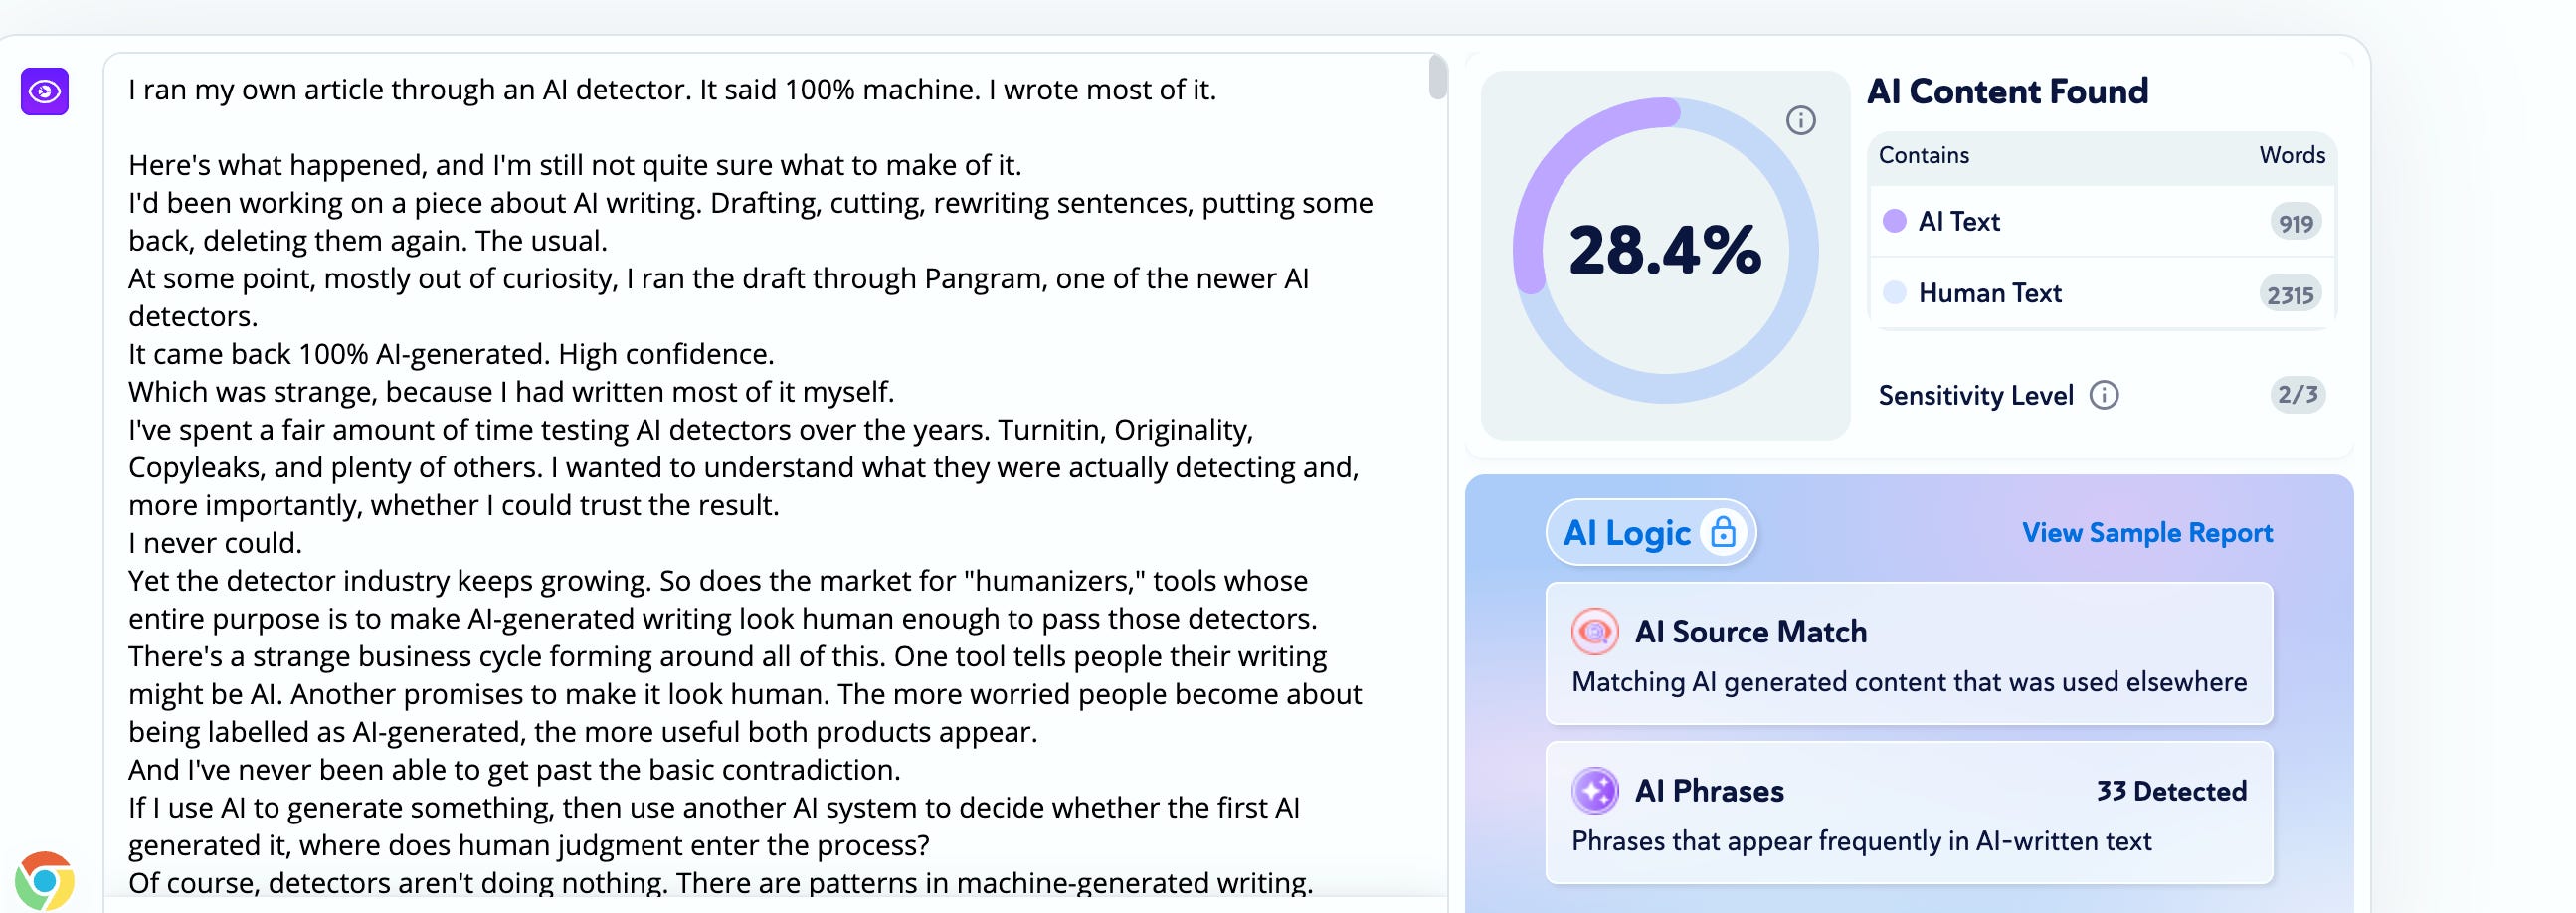
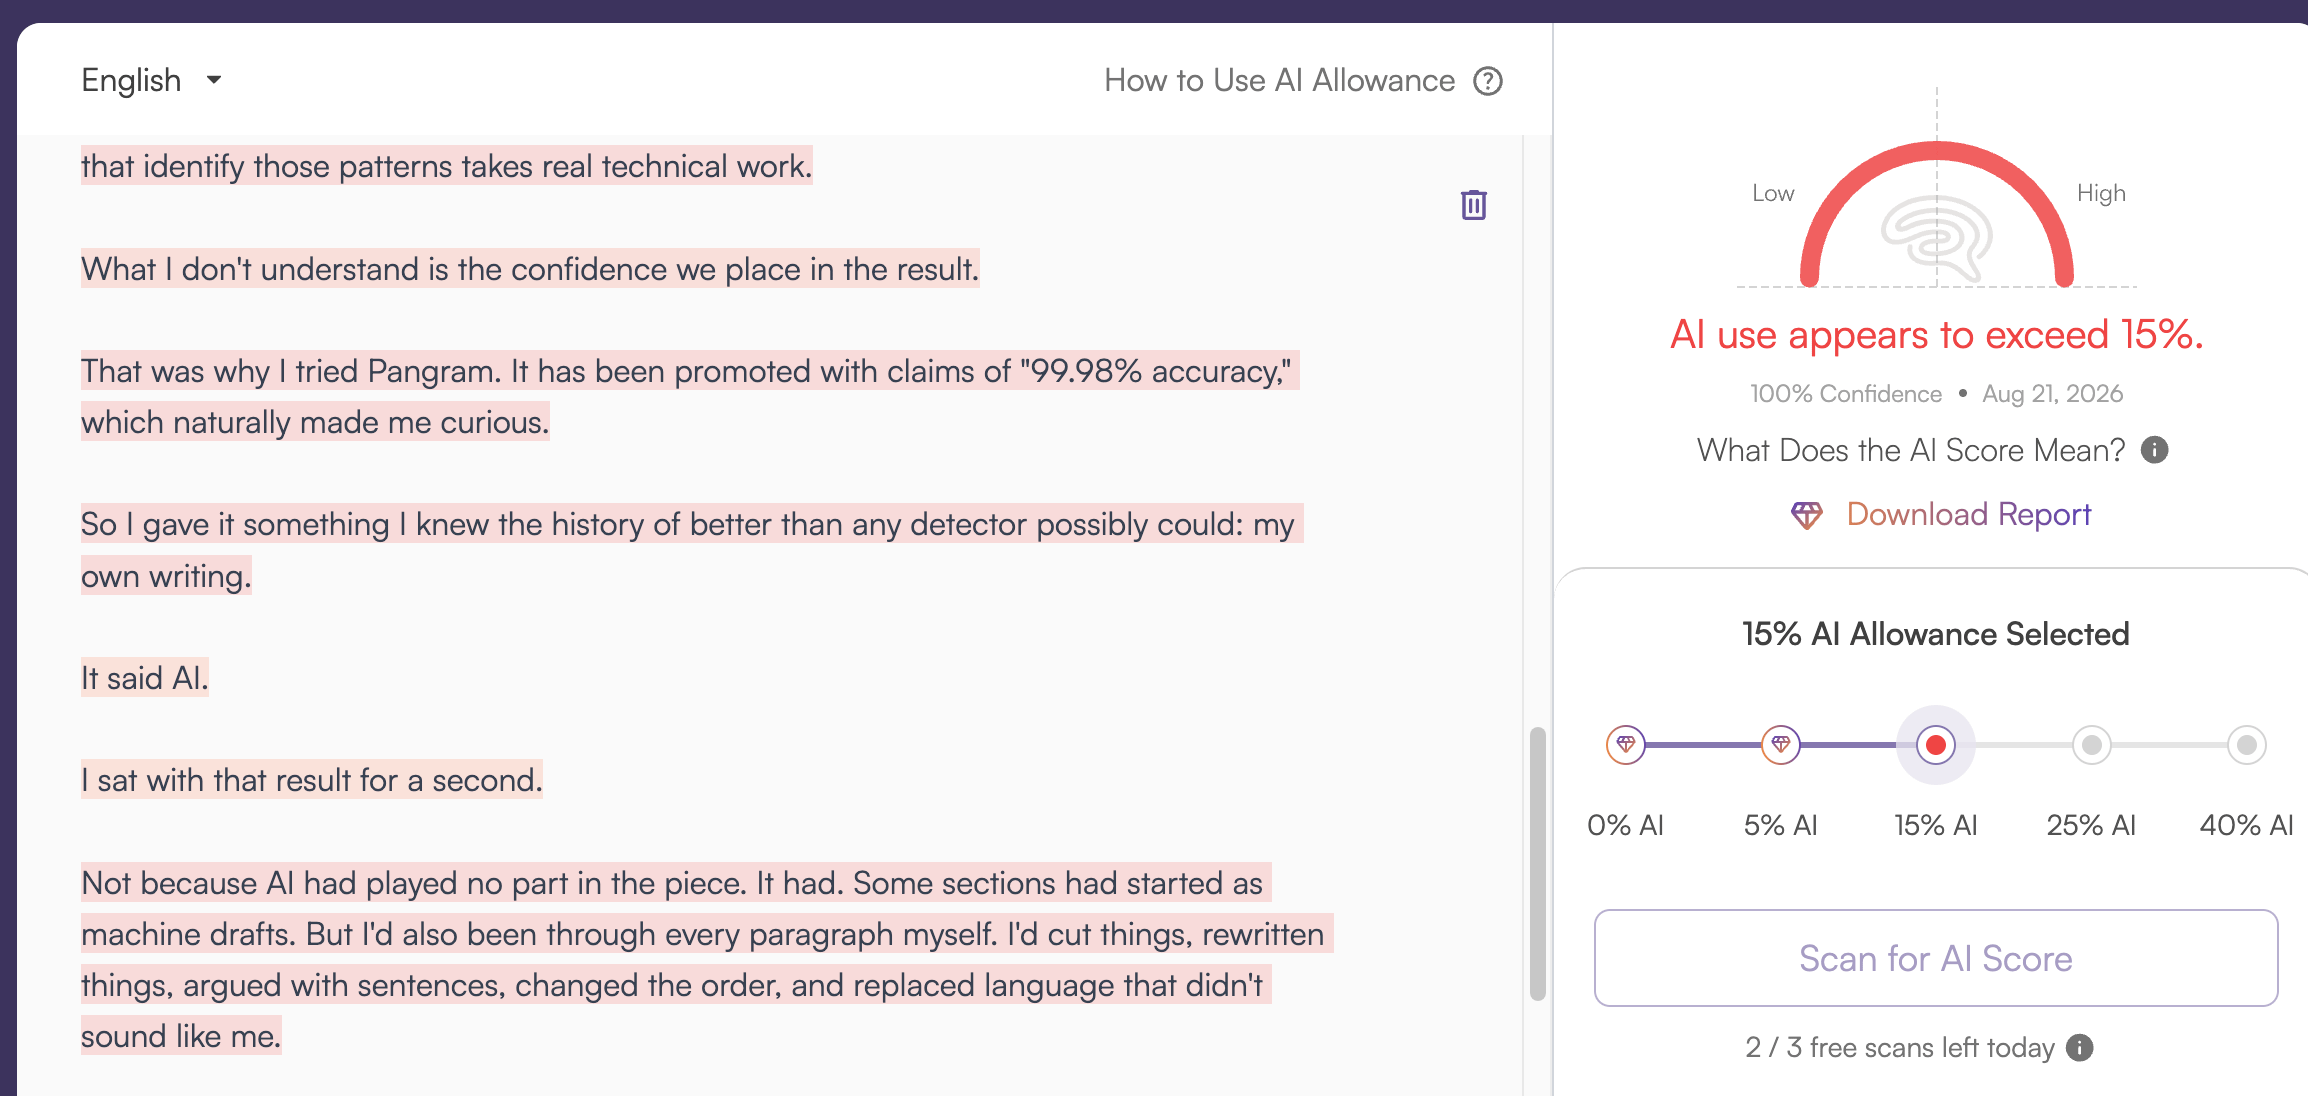
That was why I tried Pangram. It has been promoted with claims of “99.98% accuracy,” which naturally made me curious.
So I gave it something I knew the history of better than any detector possibly could: my own writing.
It said AI.
I sat with that result for a second.
Not because AI had played no part in the piece. It had. Some sections had started as machine drafts. But I’d also been through every paragraph myself. I’d cut things, rewritten things, argued with sentences, changed the order, and replaced language that didn’t sound like me.
Pangram knew none of that.
It saw the finished text and returned a number.
That gap is what interests me. There was the history of how the article had actually been made, which I knew firsthand. Then there was a piece of software making a very confident claim about that history from the finished words alone.
And around the same time, another development had me thinking about the same problem from the opposite direction.
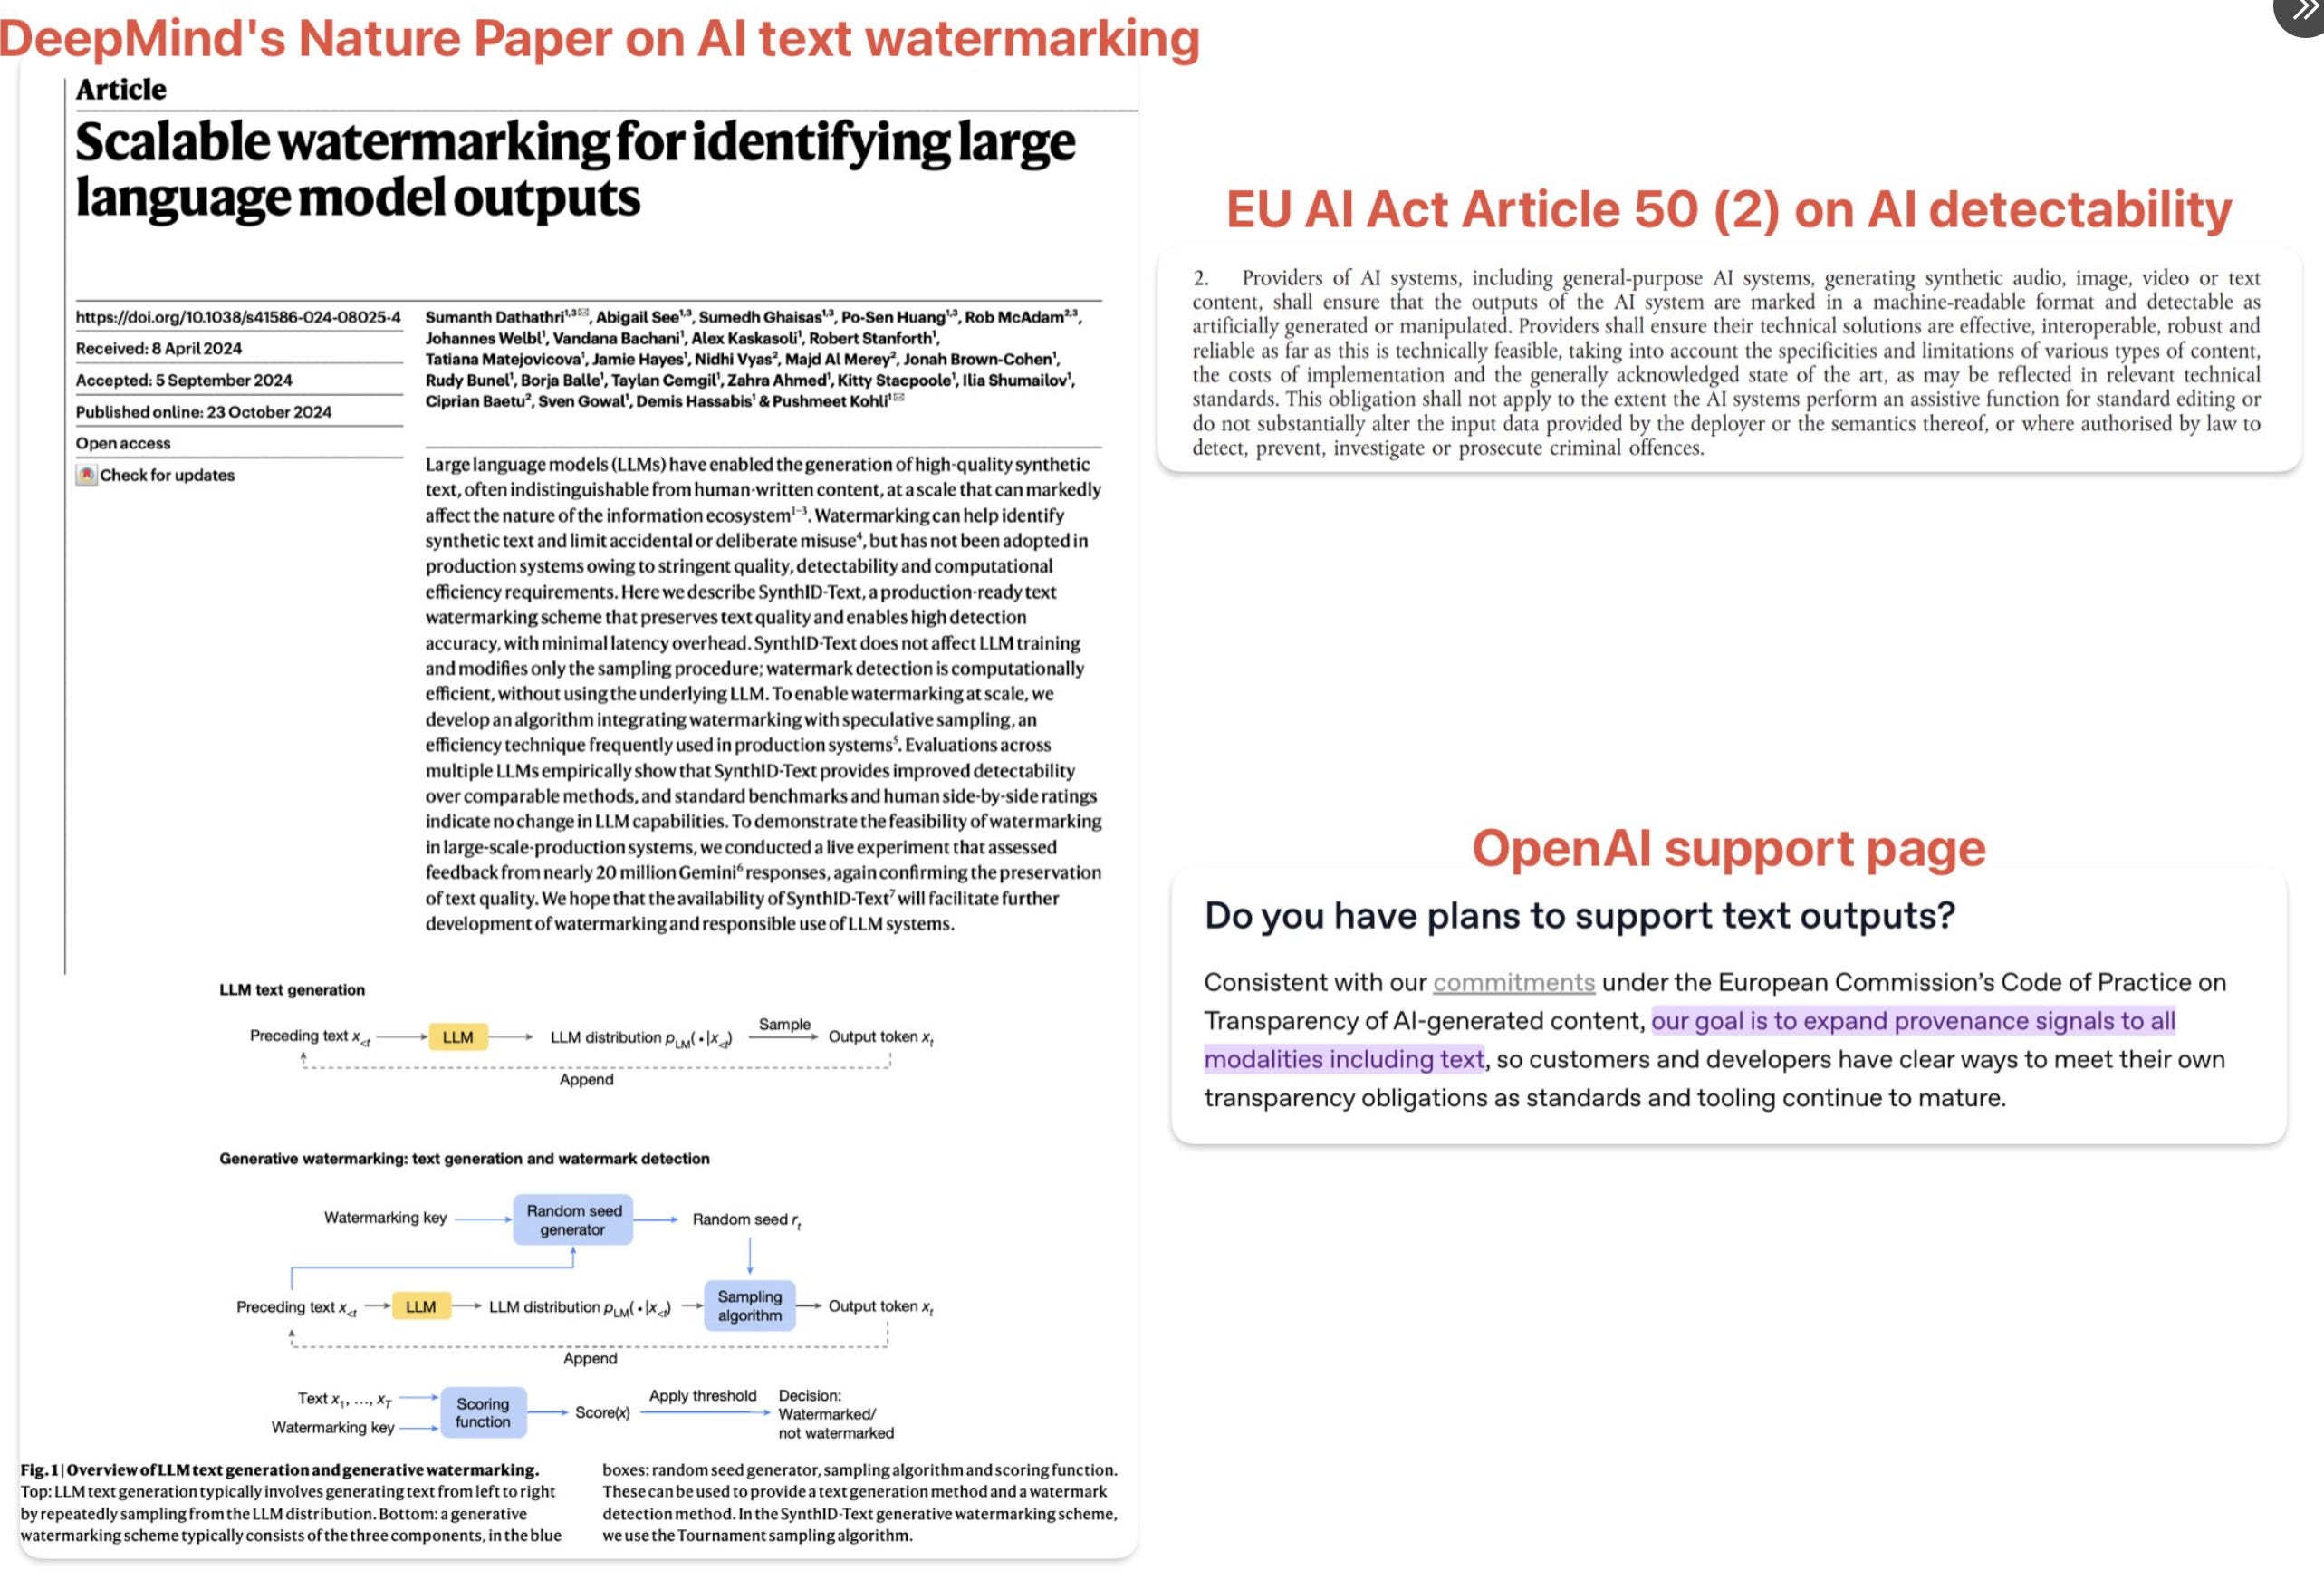
On August 12, 2026, Anthropic announced that Claude would begin putting an invisible watermark into generated text. Instead of another system looking at a piece of writing and trying to guess where it came from, the idea was to put a detectable signal there at the point of generation.
My reaction was mixed.
Part of me was relieved.
I immediately thought about programmatic SEO, automated publishing, and the enormous amount of AI content that can now be produced with almost no human involvement. If provenance becomes easier to establish, people publishing thousands of machine-generated pages may have a much harder time pretending otherwise.
But another part of the announcement bothered me.
For years, AI companies have trained models on an open web built largely from human work: articles, forums, tutorials, reviews, discussions, documentation, and countless other things people put online. Publishers once had a fairly simple bargain with search engines. You published useful material, search engines indexed it, and some of that attention came back to you as traffic.
AI changes that relationship.
Our writing helps train systems that can now produce competing writing. Those systems are then sold back to us as products. Meanwhile, the original websites may receive fewer visits because people can get an answer without ever reaching the source.
There is something uncomfortable about that arrangement.
So yes, part of me was glad to see friction being introduced for mass AI publishing.
But once I thought about the watermark itself, I realized it doesn’t solve the problem that Pangram had just demonstrated to me.
In some ways, it may make that problem more complicated.
The detector never knew anything
This is the part I think gets lost whenever people talk about AI detectors.
Pangram didn’t open my document and find some hidden flag saying, “Claude was here.” There was nothing like that for it to find.
It looked at the writing and made an inference.
That’s what Pangram, ZeroGPT, Turnitin, Originality, Copyleaks and most traditional AI detectors are doing. They’re looking for statistical patterns associated with machine-generated text.
Two terms come up a lot here: perplexity and burstiness.
Perplexity, roughly speaking, has to do with how predictable the next word is based on what came before it. Burstiness looks at variation in things like sentence length and structure.
Human writing can be messy in ways machine writing often isn’t. We write a long sentence because we’re trying to get a complicated thought out, then follow it with three words.
Like this one.
We interrupt ourselves. Change direction. Repeat things. Use a strange word because it happens to be the word that came to mind.
AI-generated writing, especially without much prompting or editing, can be more statistically regular.
Detectors look for signals like these and produce a probability.
That’s an important distinction.
They infer. They don’t know.
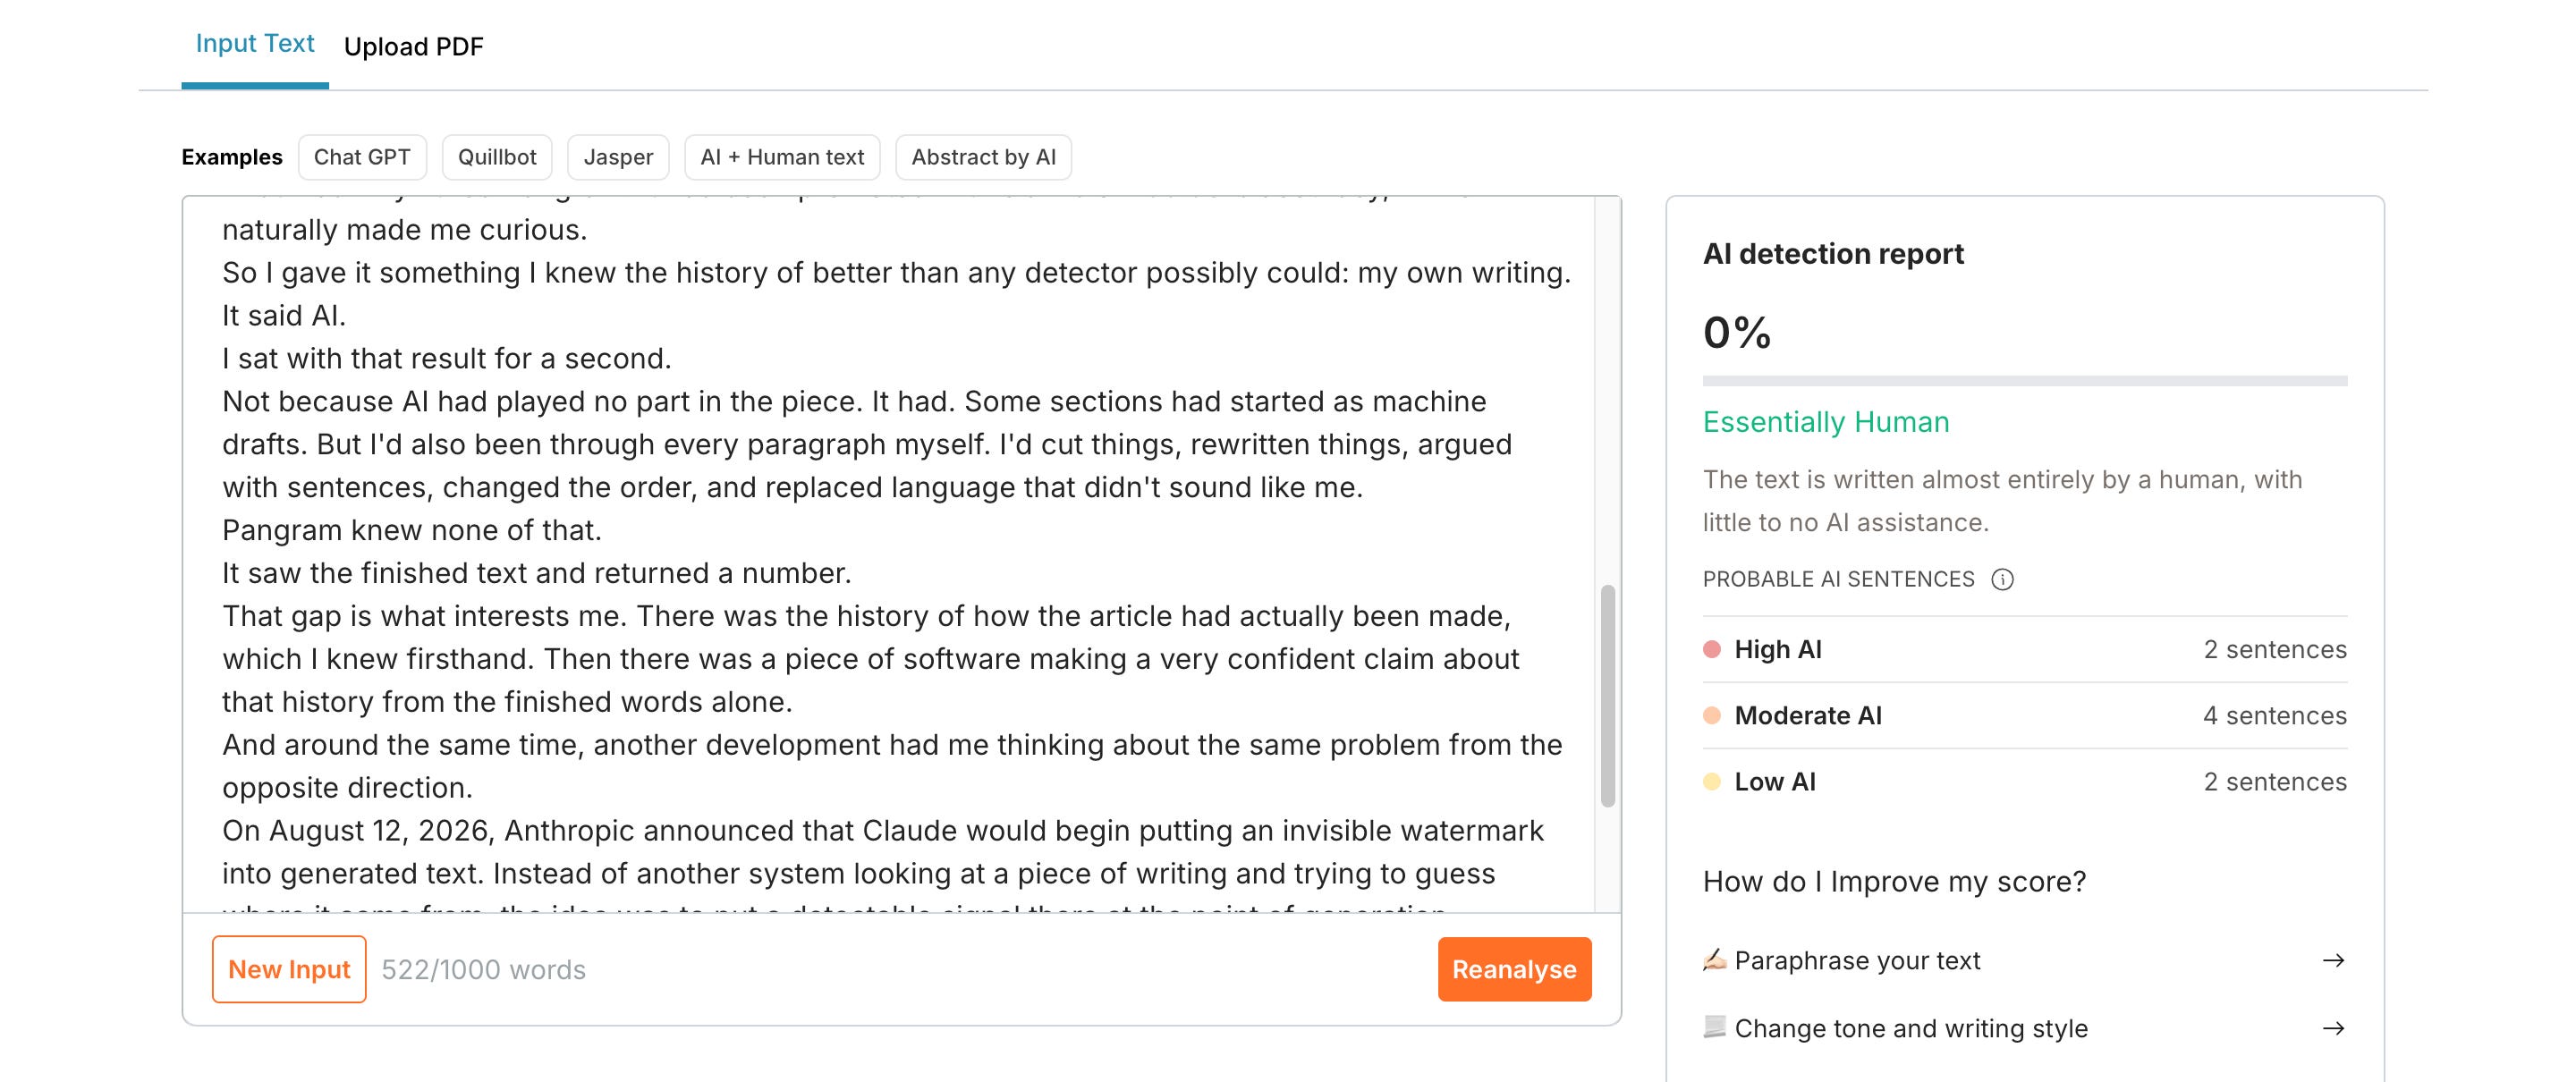
So when Pangram gave my article a 100% AI score, it wasn’t producing a receipt showing who wrote it. It was saying that my writing resembled whatever its system had learned to associate with AI-generated text.
And in my case, there was an extra complication: AI really had been involved.
Some material had been machine-drafted. Then I edited it. Cut it. Rewrote it. Added my own thoughts. Removed things I didn’t agree with. Changed sentences until they sounded right to me.
Where, exactly, does the machine-written text end and the human-written text begin?
A percentage can’t tell you that.
And this stops being an interesting technical argument the moment the person on the receiving end has something to lose.
Imagine a student who writes an essay and gets told it has a 95% probability of being AI-generated.
Or a freelancer sends in work and a client runs it through a detector before deciding whether to pay.
Now the probability isn’t just a number.
It’s an accusation.
And how does someone prove that a probability is wrong?
That’s what bothers me about the whole category. We built systems designed to make statistical guesses, then started using their output in situations where people naturally interpret the number as evidence.
Those are two very different things.
What the watermark changes
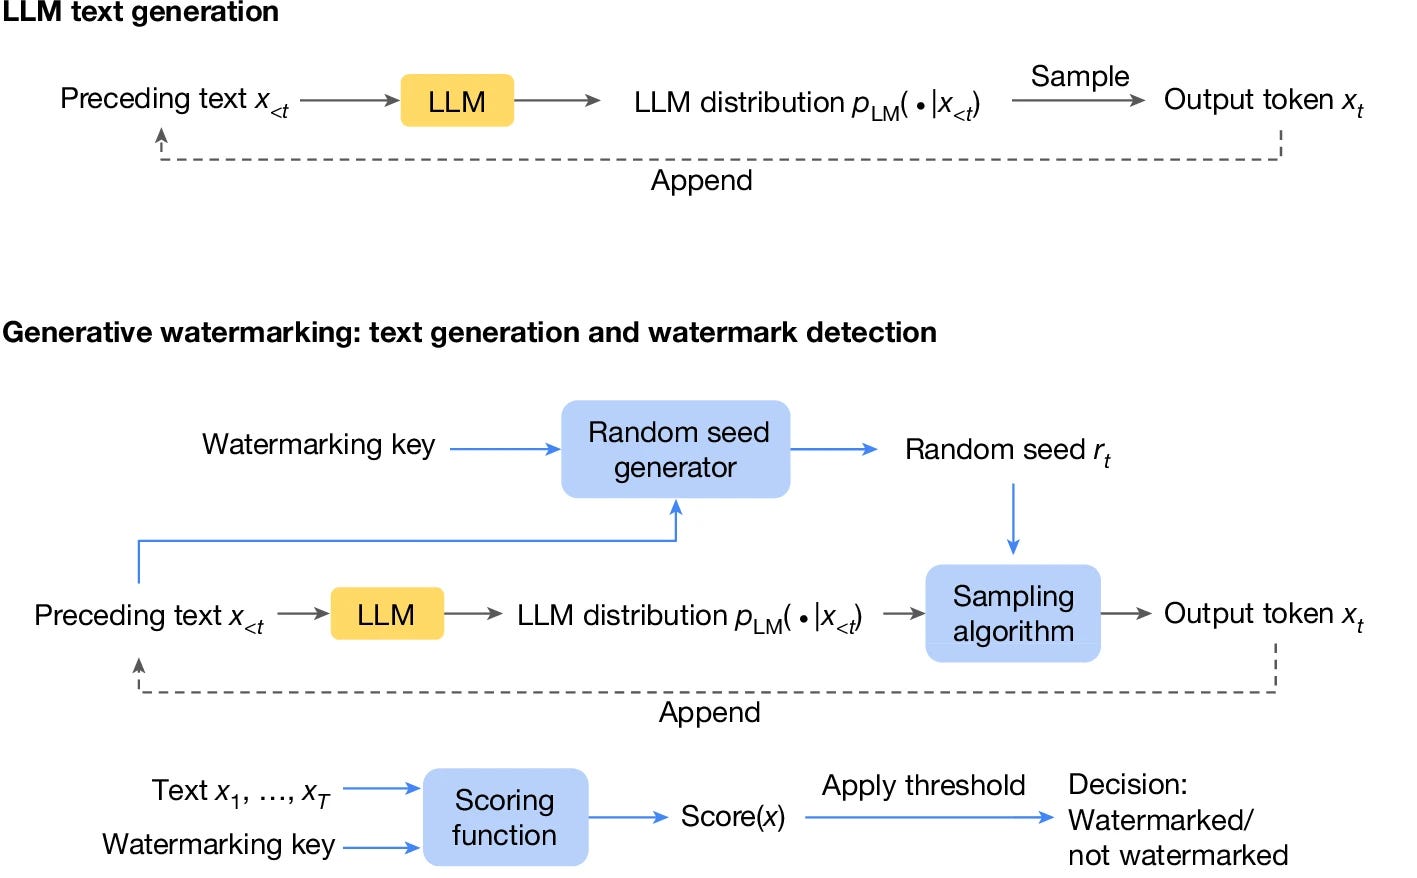
This is why the Claude watermark caught my attention.
It changes the question.
A traditional detector asks:
“Does this text look like AI wrote it?”
A watermark can ask something closer to:
“Is the signal my system placed in this text still present?”
The difference matters.
The first question requires inference. The second gives you something specific to verify.
If a model deliberately leaves a detectable pattern in generated text, you no longer have to judge authorship entirely from how the prose looks.
For once, there may actually be something there to find.
The rough idea behind text watermarking is that the model slightly influences its token or word choices during generation according to a pattern. You don’t notice the pattern while reading, but a system designed to look for it can potentially detect it later.
That means the signal can remain even after ordinary copy and paste, because it is encoded in the generated text rather than attached as simple file metadata.
There is an important caveat here.
I’ve seen technical descriptions of Claude’s approach that connect it with cryptographic signatures and C2PA-style provenance. I have not independently confirmed enough of the implementation details to present those descriptions as established fact.
So I’m deliberately separating two things: the broader idea of verifiable provenance, which is what interests me here, and the exact technical implementation Anthropic uses.
The second deserves confirmation before making strong claims about it.
But even if we assume the system works exactly as intended, another problem appears almost immediately.
A watermark is strongest when nobody is trying to remove it
Suppose Claude generates a paragraph.
You copy it.
You paste it into a blog.
If the watermark survives ordinary copying, the signal goes with it.
Fine.
But now imagine someone actually wants to hide the origin.
They rewrite the passage substantially.
Or pass the ideas through another model and generate new wording.
Or otherwise reconstruct enough of the text that the original token choices disappear.
At some point, the pattern you’re trying to detect has been changed along with the words carrying it.
And that creates a strange imbalance.
The person who casually uses Claude and pastes the result somewhere may preserve the signal.
The person deliberately trying to conceal large-scale AI generation has an incentive to remove or disrupt it.
That’s almost the opposite of what you’d want from an authorship test.
It doesn’t make watermarking useless. It means we need to be precise about what problem it solves.
There’s another limitation that matters just as much.
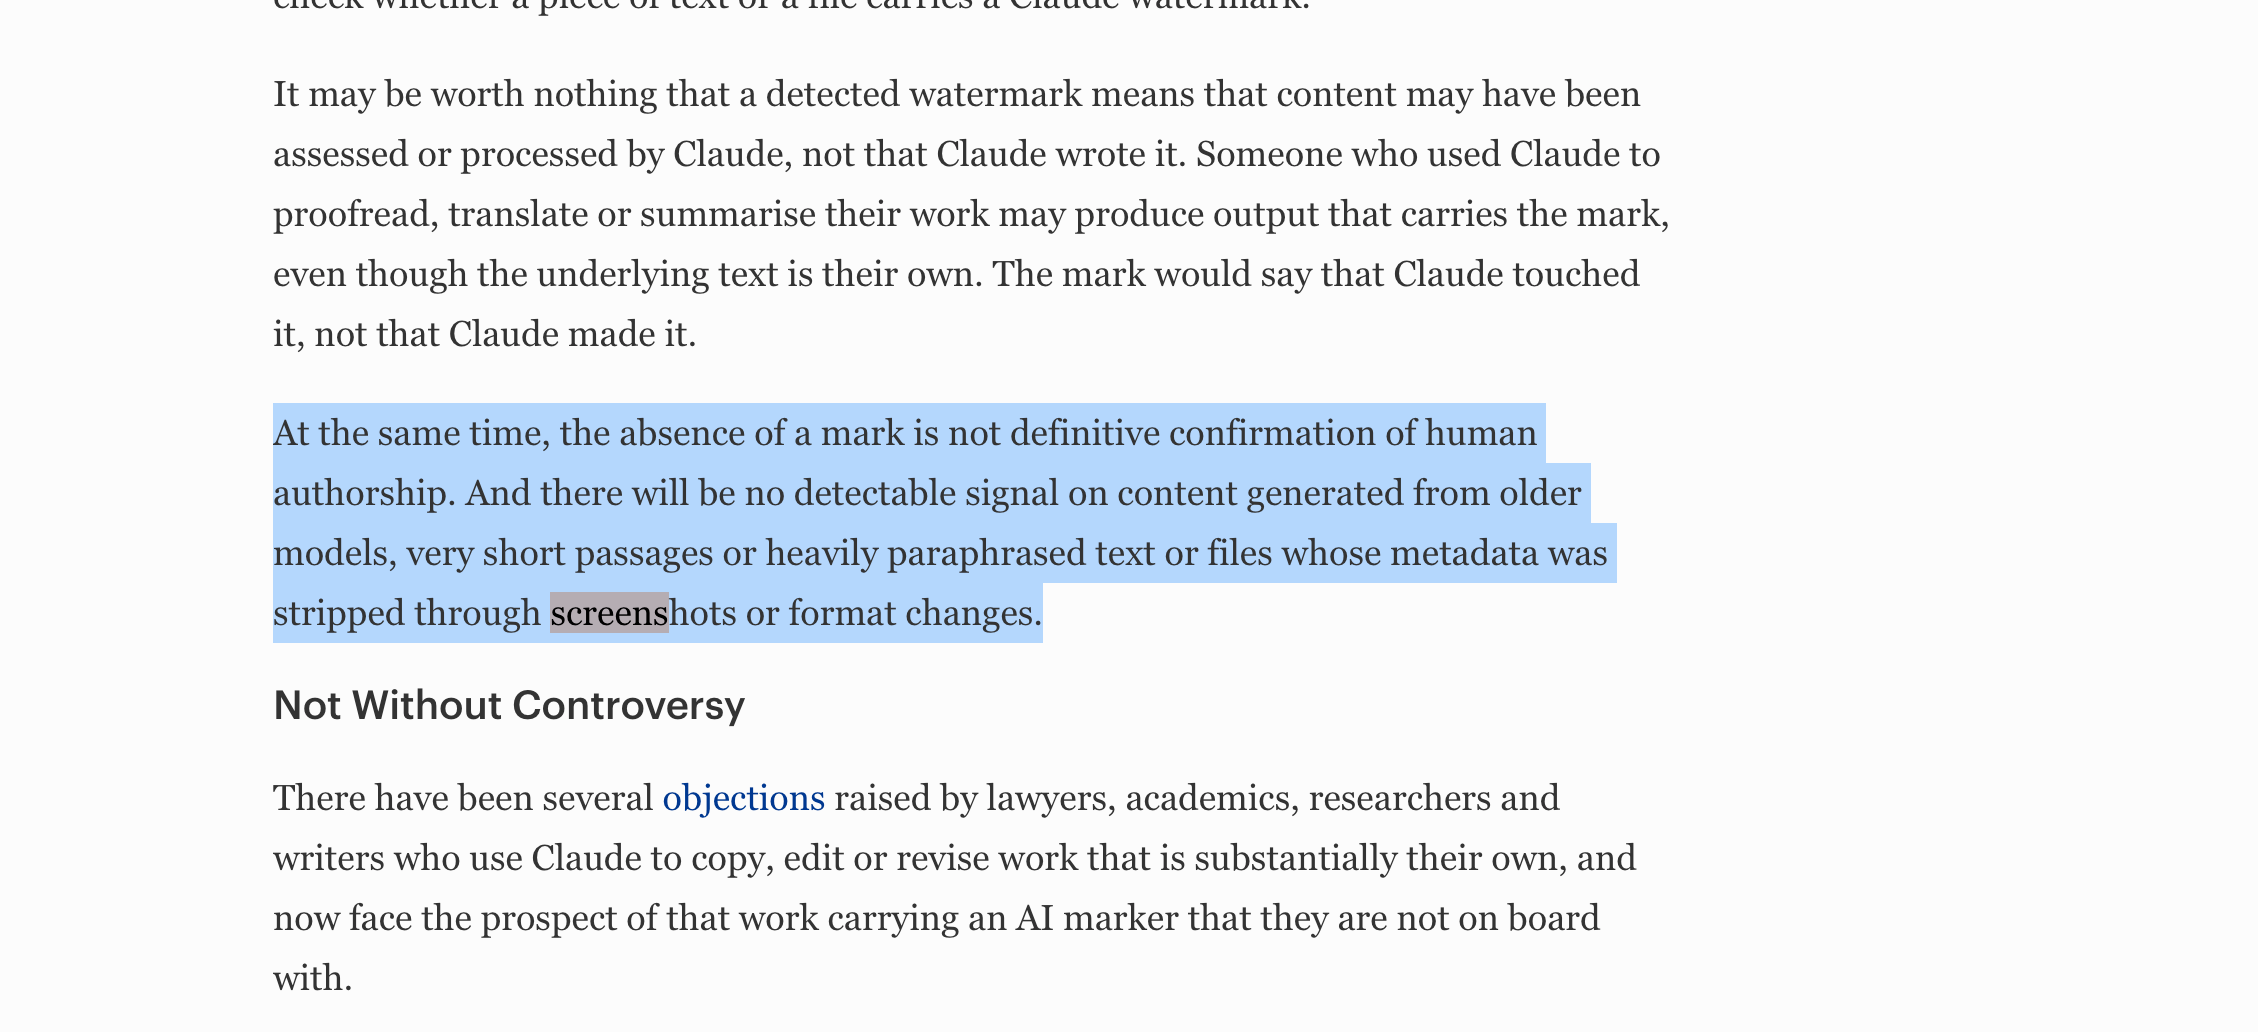
A Claude watermark can tell you something about Claude-generated text.
What does it tell you about text generated by another model?
Nothing.
What about an open-source model running locally without a watermark?
Again, nothing.
So even a perfect Claude watermark cannot answer the broader question people keep asking:
“Was this written by AI?”
It can answer a narrower question:
“Does this contain the signal associated with Claude-generated text?”
That’s a much more defensible question.
It’s also a much smaller one.
What a watermark actually proves
There is another problem hiding underneath all of this.
Suppose the watermark works perfectly.
The detector finds it.
No ambiguity. No false positive. The text definitely passed through Claude.
What have we proved?
That it passed through Claude.
Not that Claude came up with the ideas.
Not that a human didn’t write the original draft.
Not that the claims are false.
Not that the writing is bad.
Imagine I spend two days writing an article myself, then give it to Claude and ask:
“Fix the grammar and make this easier to read.”
If Claude’s rewritten output carries a watermark, the final article may now be identifiable as Claude output.
But what does “AI-generated” mean in that situation?
The argument is mine.
The research is mine.
The examples are mine.
Much of the language may still be mine.
Claude was part of the editing process.
A provenance system can tell us something useful about that process. But provenance and authorship aren’t identical, and provenance certainly isn’t fact-checking.
Knowing where words came from tells you nothing, by itself, about whether those words are true.
And that brings me straight back to the Pangram result.
We’ve become obsessed with answering:
Human or AI?
I’m increasingly unsure that’s the question we should be organizing everything around.
A human can write something inaccurate, derivative, useless, or completely fabricated.
AI can be involved in producing something carefully researched and genuinely useful.
The label alone doesn’t settle the quality of the work.
Google’s public guidance around AI-generated content has reflected a similar distinction for some time. The important question is not simply whether automation was involved. The concern is whether content is being produced primarily to manipulate rankings rather than help people.
That seems much closer to the question worth asking.
Not: “Did AI touch this?”
But: “Why does this exist, and is it any good?”
So can you remove a Claude watermark?
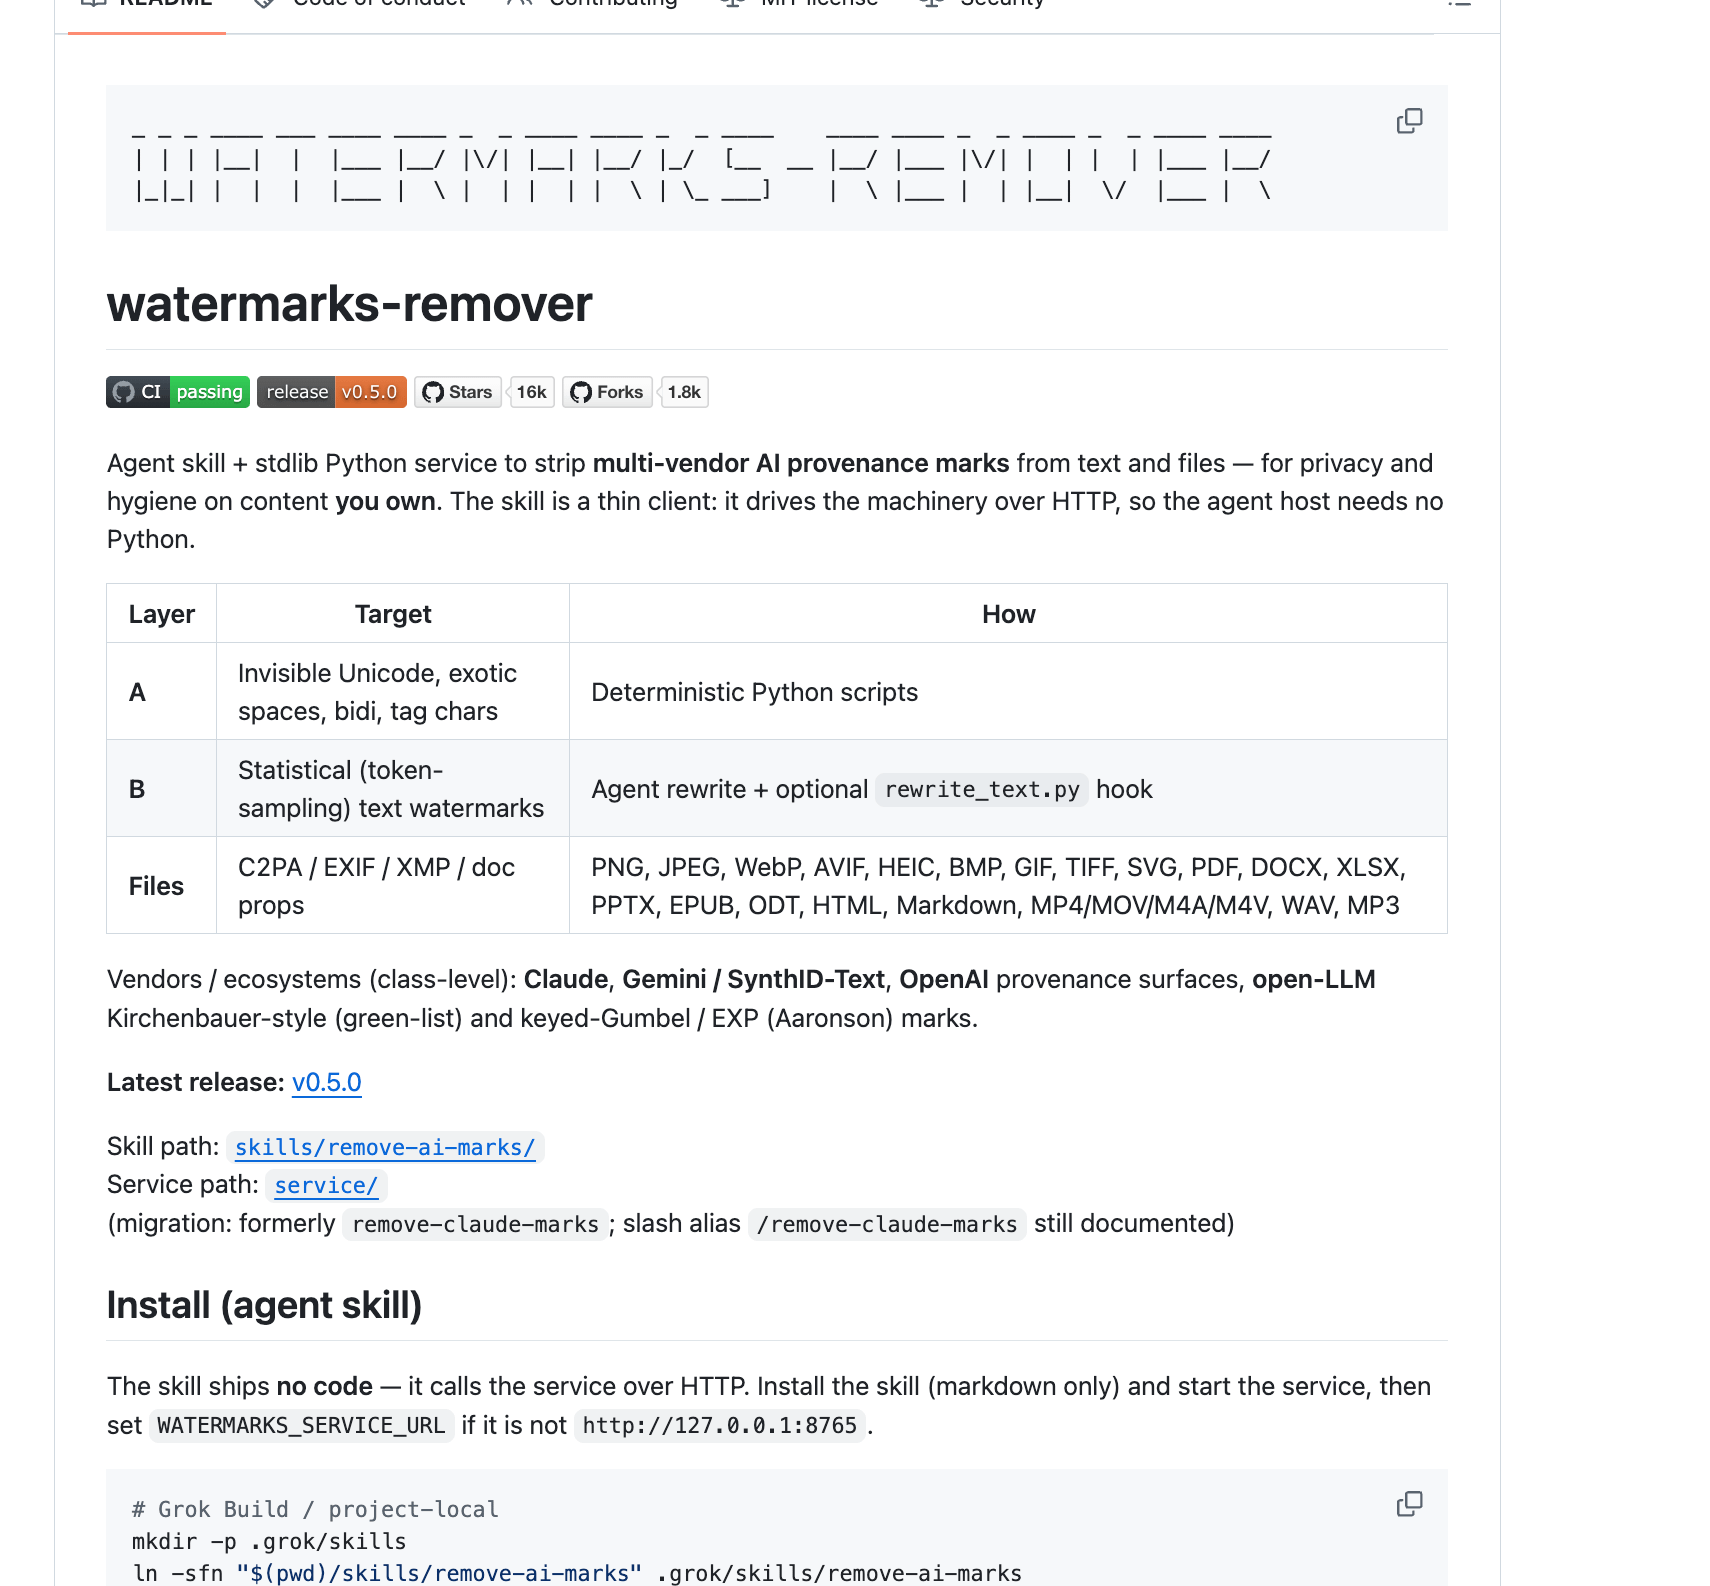
This is probably the question that will bring a lot of people to this article.
And I think the wording matters.
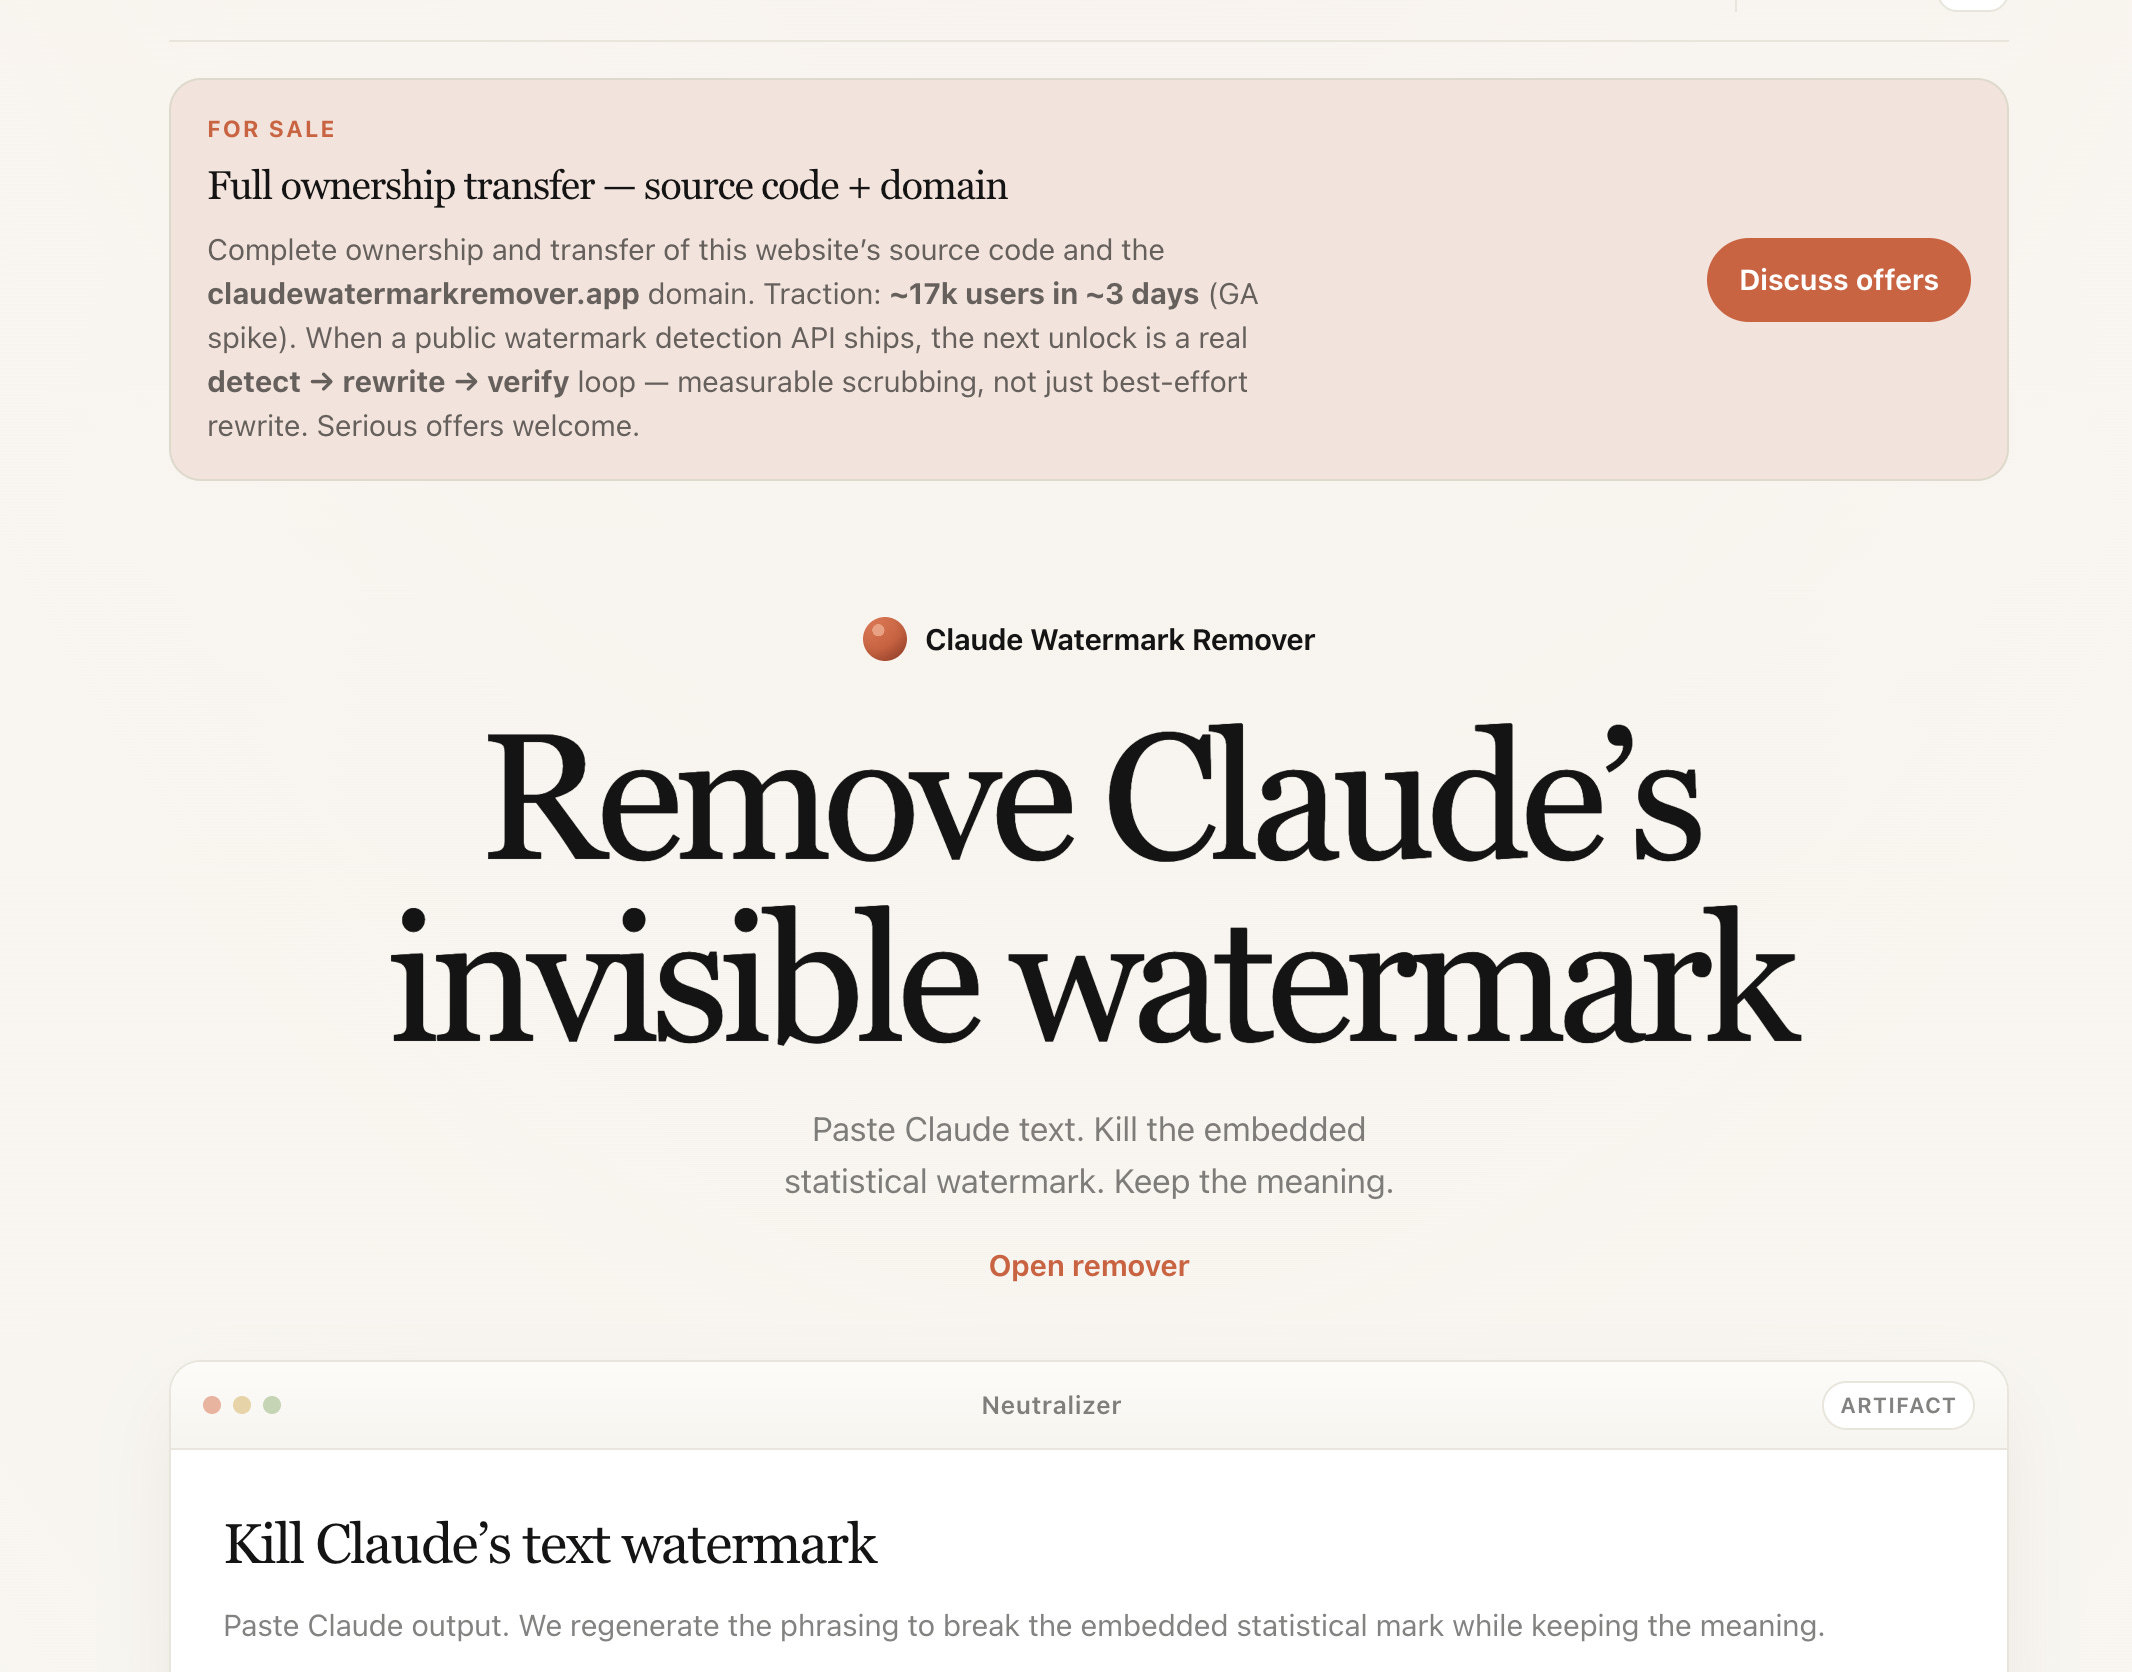
If a watermark depends on patterns embedded in generated wording, then sufficiently changing that wording may also change or destroy the signal.
But nobody should be promising that some particular rewrite, paraphraser, screenshot workflow, or “humanizer” will reliably produce a clean result against every current and future detection method.
That’s just the detector industry starting another sales cycle.
More importantly, look at what happens when you genuinely rewrite something.
You read the draft.
You decide what you agree with.
You throw out the parts you don’t.
You reorganize the argument.
You replace language that isn’t yours.
You add things the model didn’t know.
You remove things you would never say.
Eventually, you’re not merely trying to make the detector return a different number.
You’re writing.
That distinction matters to me.
If you take a Claude-generated draft and genuinely rework it, the provenance of the final text really has changed. Human decisions now exist throughout it.
That’s different from running the same draft through a tool whose only purpose is to make another tool classify it differently.
So if someone asks me for the most reliable way to make AI-assisted writing sound like their own writing, my answer is boring:
Do the writing.
Use AI for research if it helps.
Use it to challenge an argument.
Ask what you’ve missed.
Use it to organize messy notes.
Use it to find holes in your reasoning.
But when the words matter, put yourself back into the process.
Not because you’re trying to beat a detector.
Because you’re putting your name on the result.
Watermark Remover : https://github.com/guillaumemeyer/watermarks-remover
Claude Watermark Remover: https://claudewatermarkremover.app/
Are we back where we started?
In some ways, yes.
Generation improves.
Detection improves.
Providers introduce provenance systems.
People find ways around them.
Those systems improve again.
That cycle isn’t going away.
But I don’t think watermarking leaves us exactly where we started.
Before, a detector could look at a passage and say, “This resembles AI-generated text.”
With reliable provenance, there are situations where a system may be able to say something much narrower and much stronger:
“This signal was placed here when the text was generated.”
That’s progress.
Limited progress, but still progress.
The problem comes when we stretch that narrow fact into a much larger conclusion.
A watermark doesn’t prove that a person contributed nothing.
The absence of a watermark doesn’t prove that a person wrote everything.
And an AI-detection score certainly doesn’t give us enough information to accuse somebody of dishonesty on its own.
Maybe that’s the rule we should have had from the beginning.
Treat detection as a signal.
Treat provenance as evidence about origin.
Treat neither as a verdict on authorship, accuracy, or quality.
Especially when someone’s grade, payment, job, or reputation depends on the conclusion.
Where I landed
I started with a detector telling me that an article I’d spent hours working on was 100% machine-generated.
That irritated me.
But the more I thought about it, the less interested I became in proving the detector wrong.
Because there’s a bigger change happening underneath all of this.
For a long time, fluent writing carried a certain assumption with it.
If something was coherent, polished, and reasonably thoughtful, we assumed a person had sat down and written it.
That shortcut is gone.
AI can produce fluent prose in seconds.
So fluency no longer tells us very much about authorship. And authorship, by itself, never told us as much about quality as we liked to pretend.
Maybe that’s why we’re so desperate for detectors.
We want the percentage.
We want the label.
We want something to tell us, confidently, what we’re looking at.
Because the alternative requires judgment.
Who produced this?
What role did AI actually play?
Where did the information come from?
Can I verify the claims?
Did somebody think about what they’re saying before publishing it?
And, after all of that, is this worth reading?
Those questions take longer than dropping text into a detector and waiting for a dial to move.
But they’re the questions that survive regardless of how good generation, detection, or watermarking becomes.
A detector can give you a probability.
A watermark may give you provenance.
Neither can decide whether the thing in front of you deserves your trust.
That part is still up to you.
What people will do next
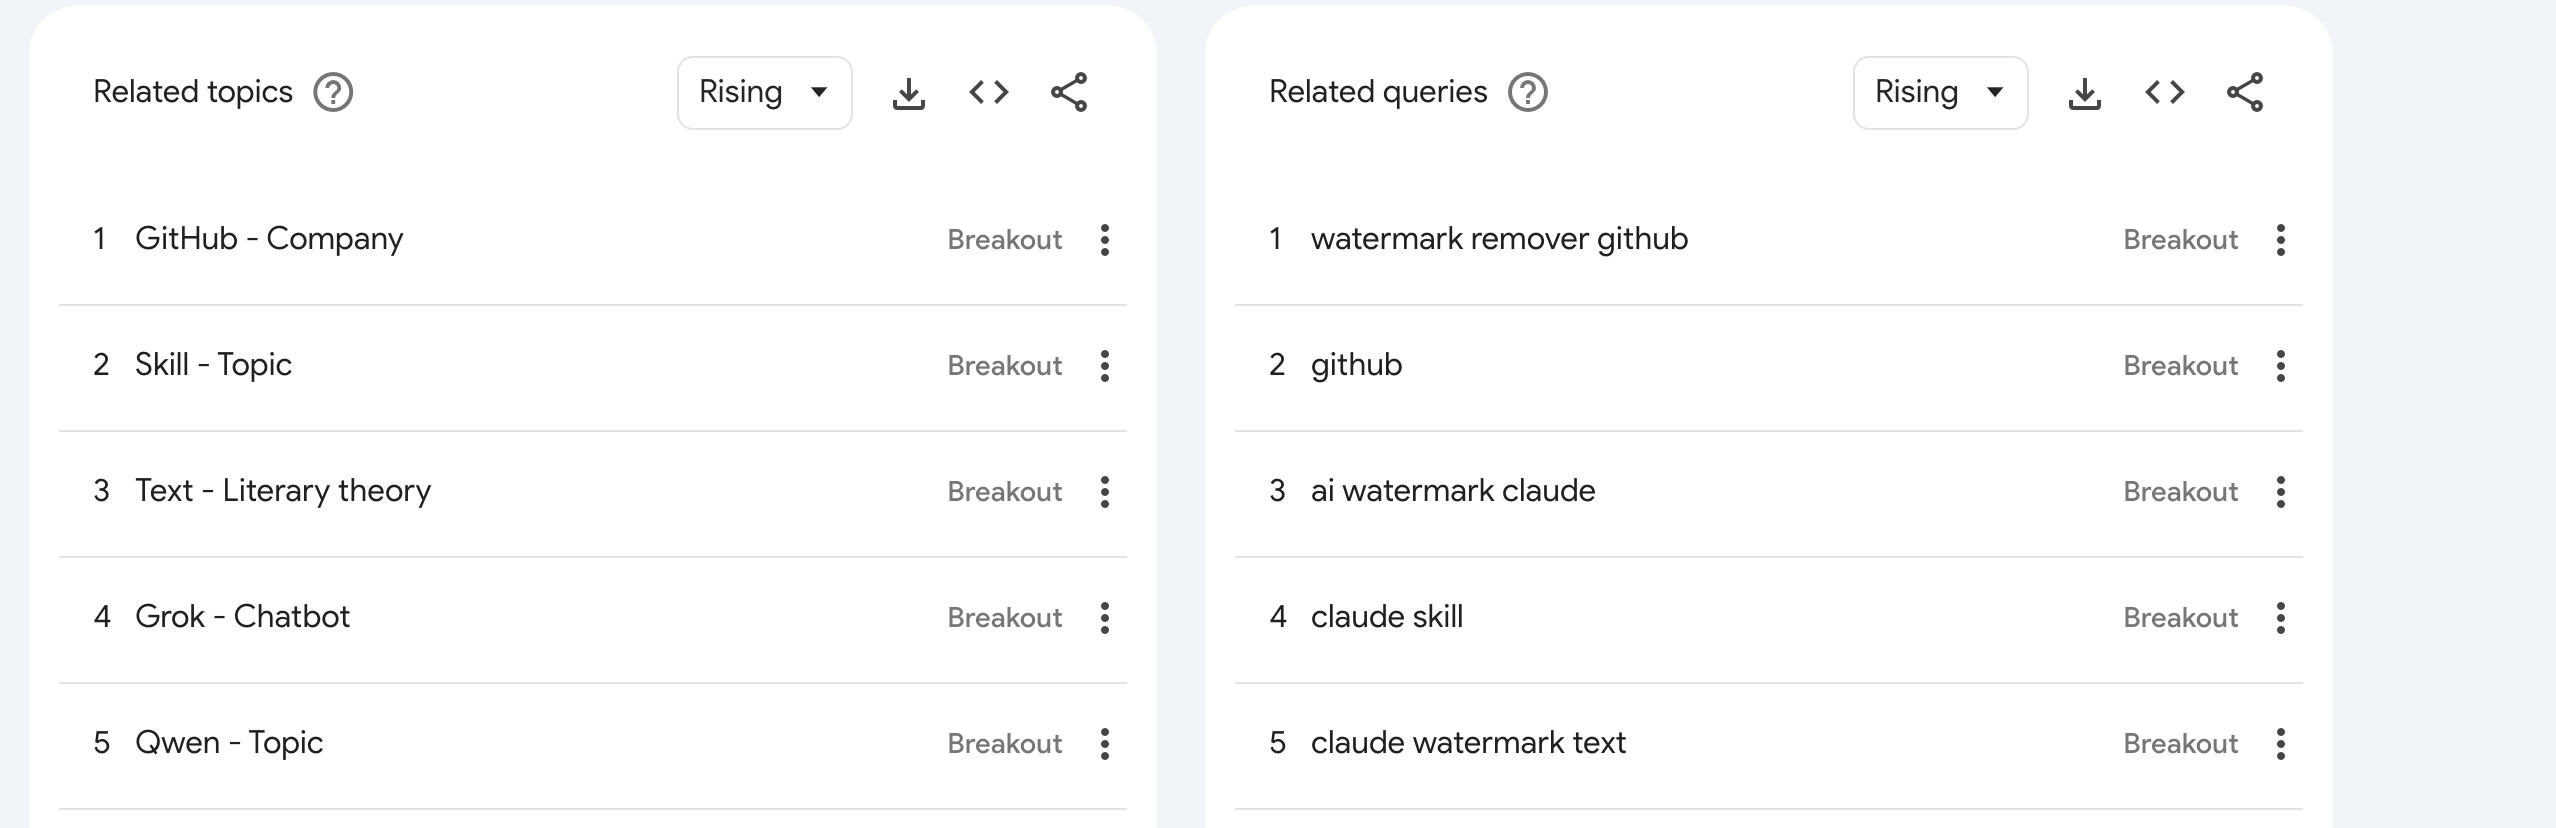
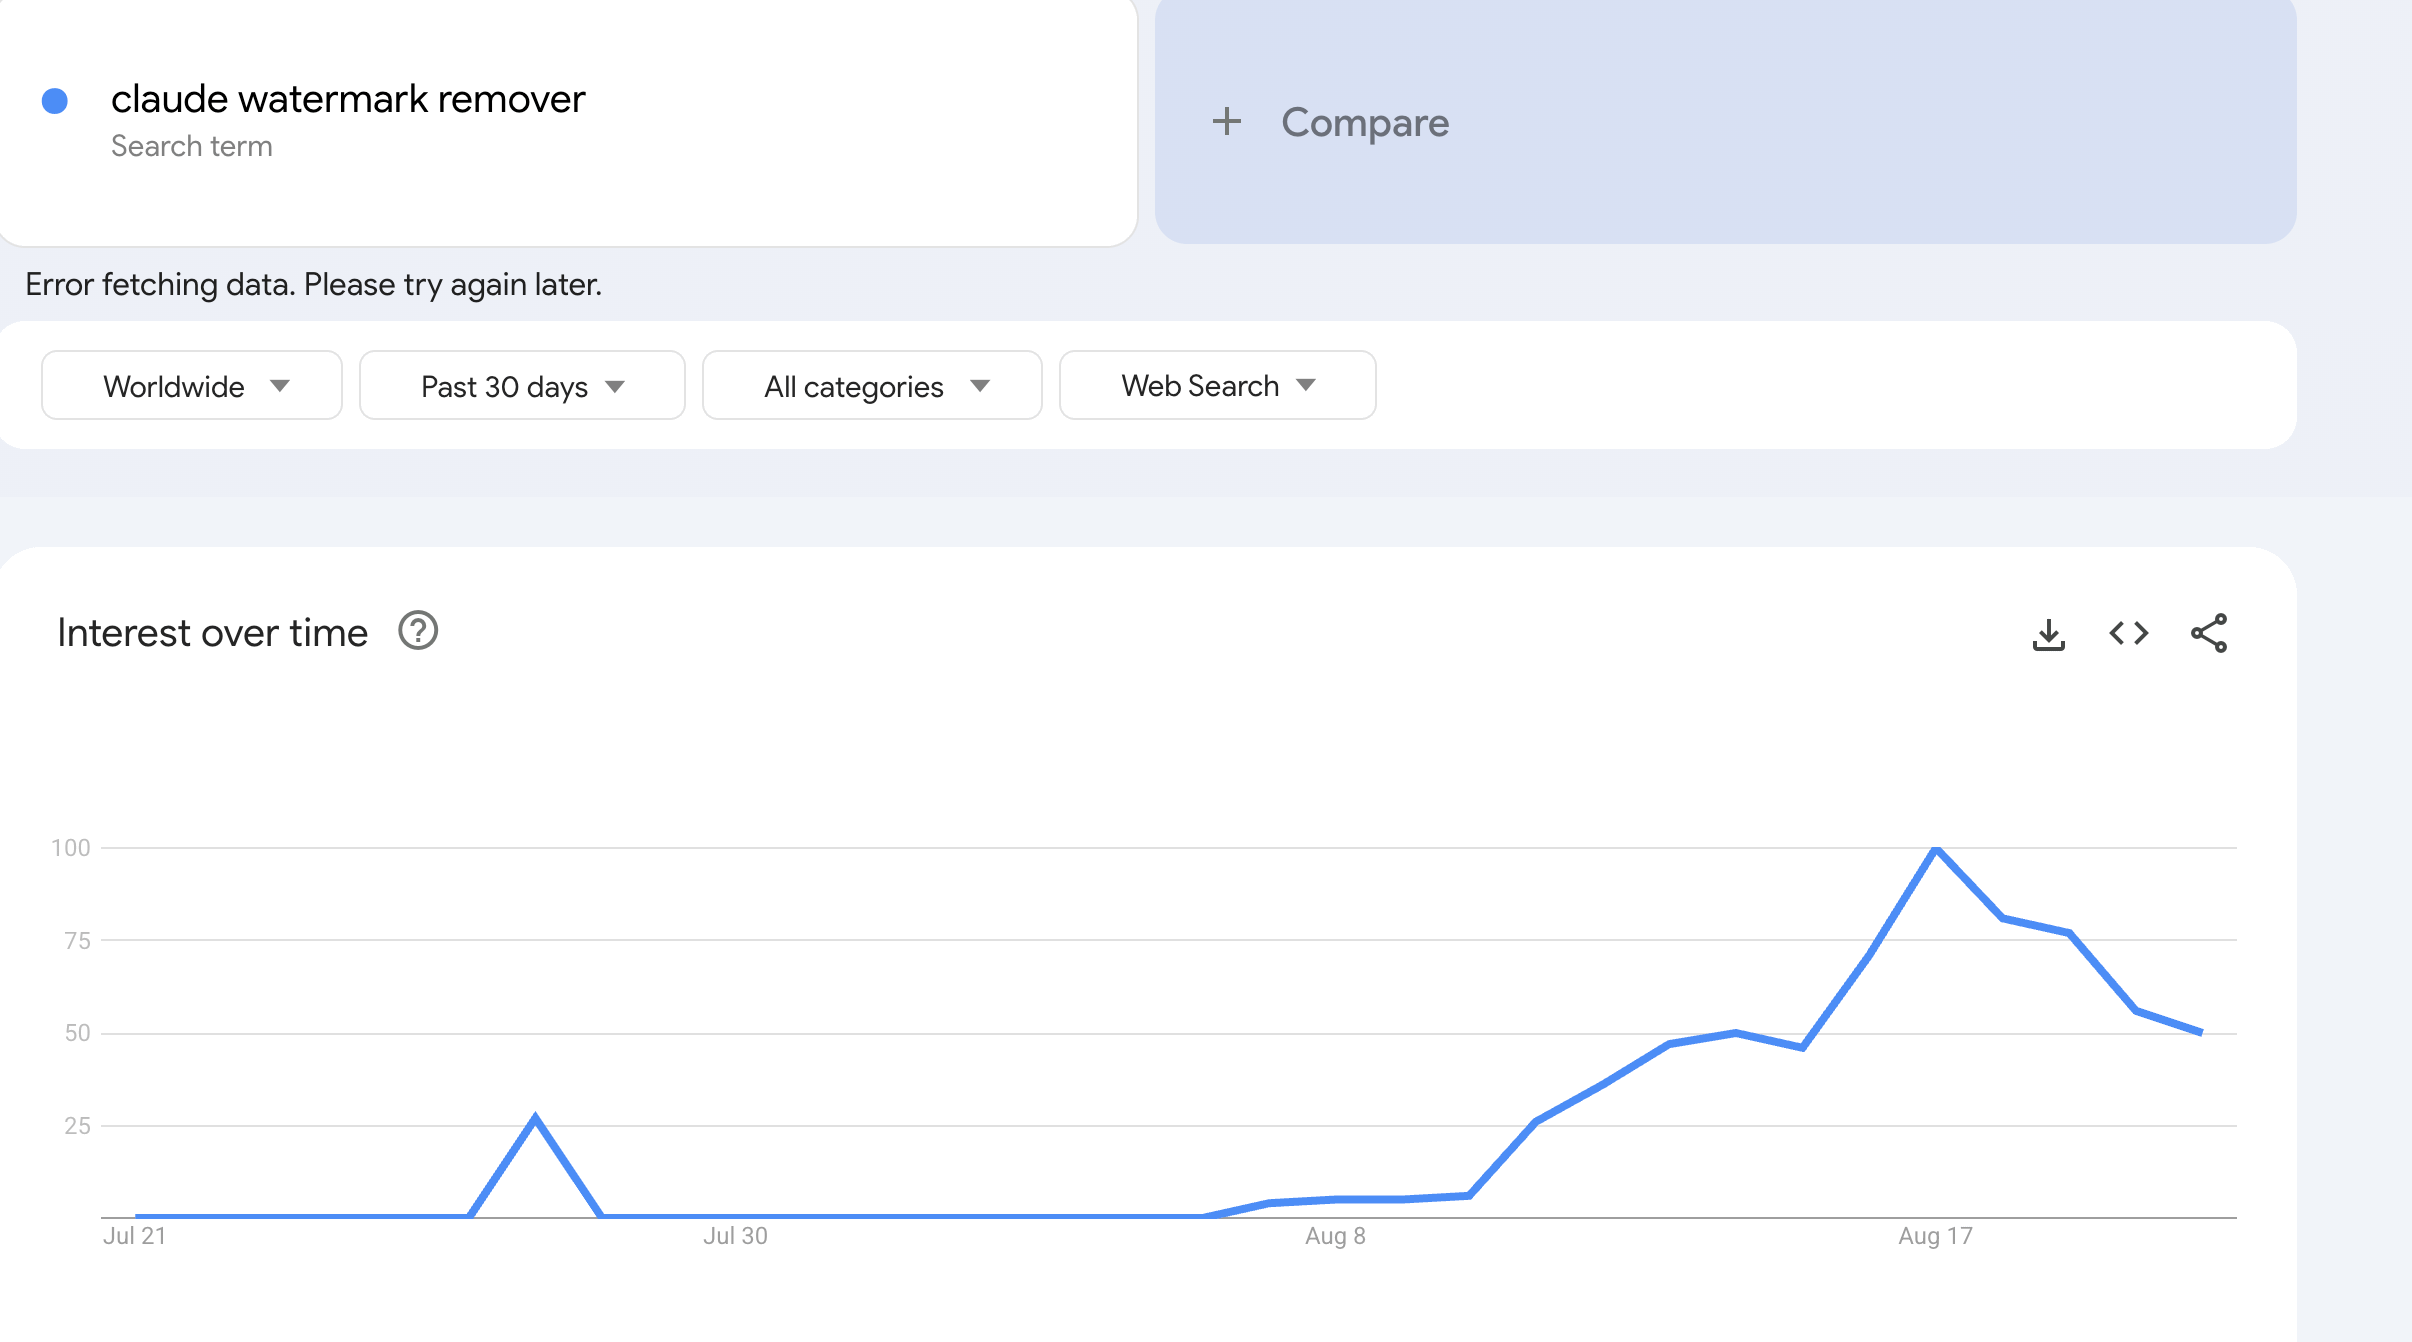
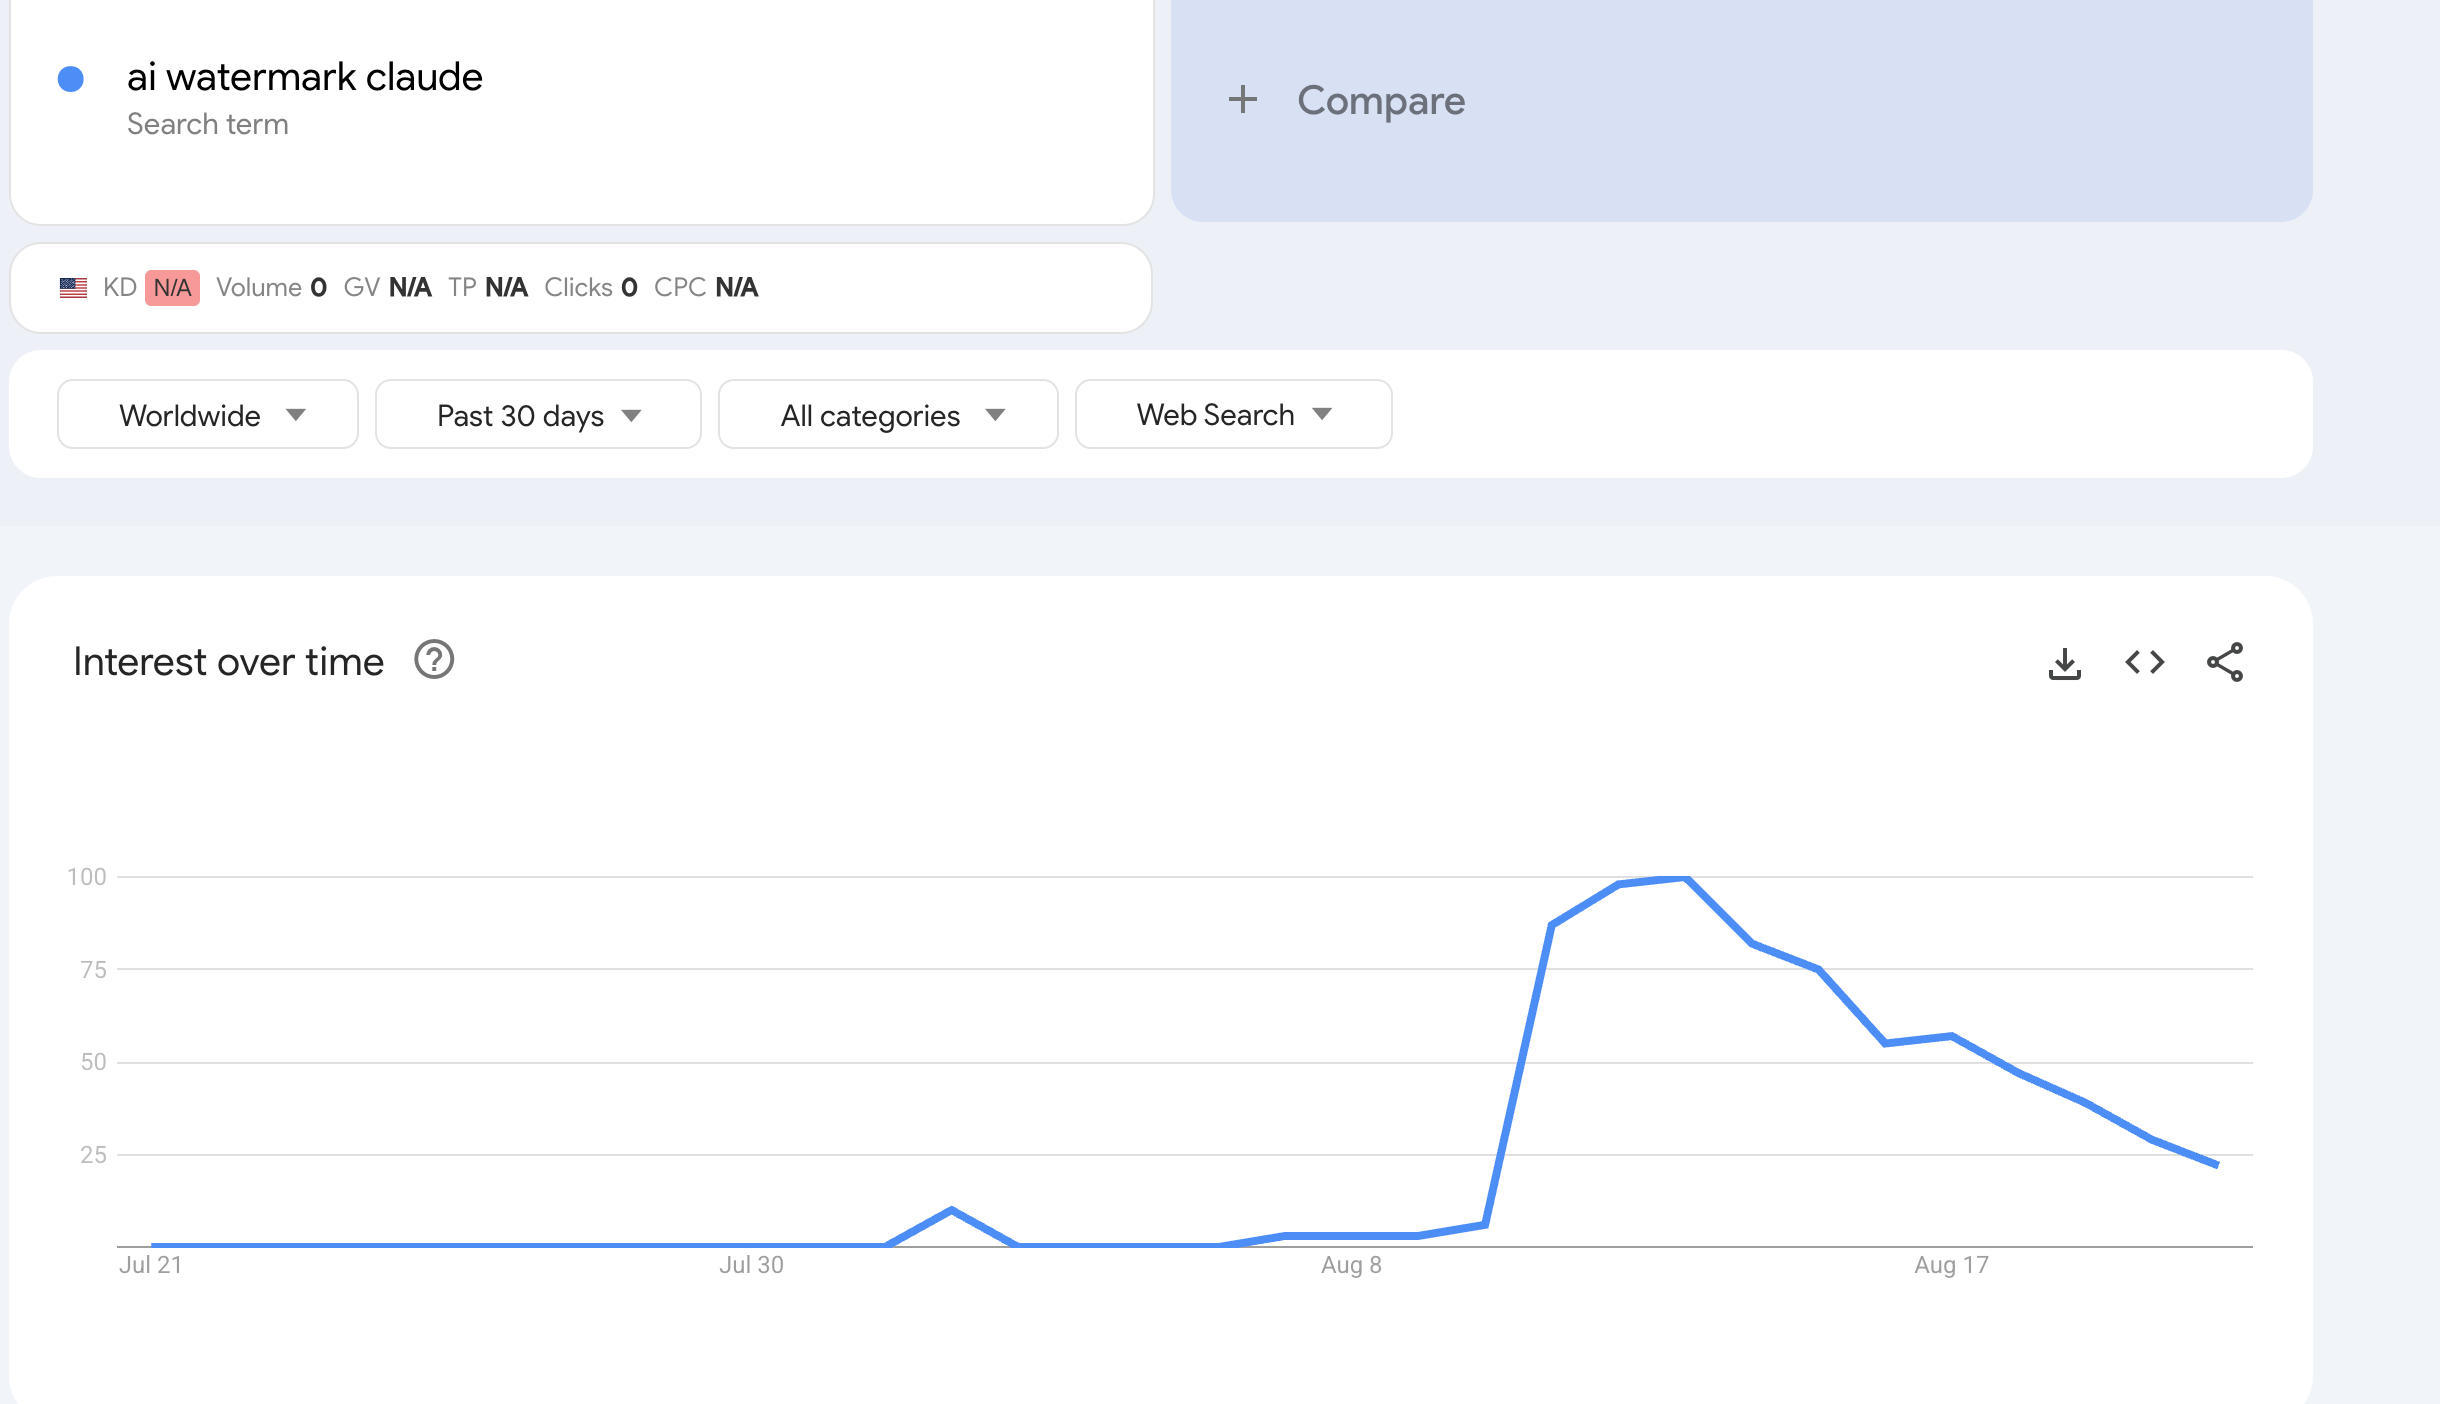
The funniest part is that the workaround conversation started almost immediately.
I’ve already seen variations
Running content via notepad on windows
Then there are more elaborate versions:
“Send each sentence through a different model. Now the watermark is gone.”
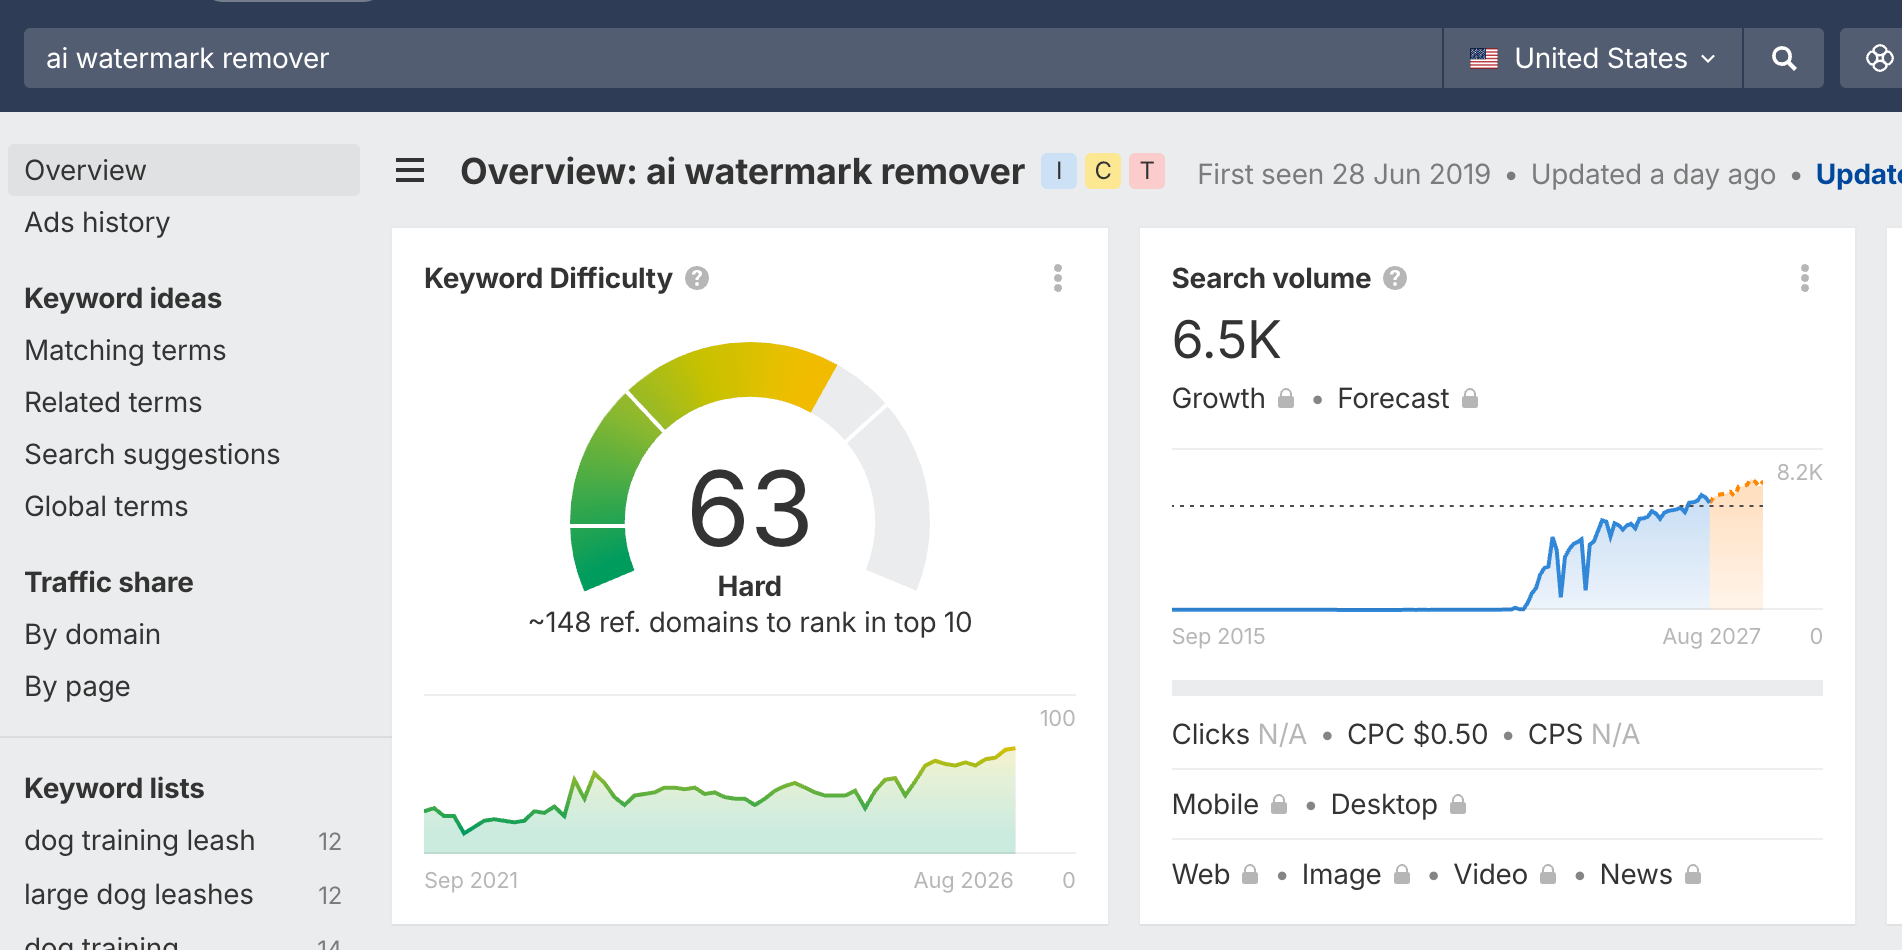
Others suggest changing a few words, correcting the grammar, using a “humanizer” prompt, or simply moving the content to another model altogether.
Some people had already moved from Claude to Codex because of the watermark.
Whether every one of these methods actually removes a specific watermark is a different question. I wouldn’t trust anyone making that promise without evidence.
But the reaction itself tells you something.
The moment you introduce a detectable signal, people start designing workflows around avoiding that signal.
And with AI, the number of possible transformations is enormous.
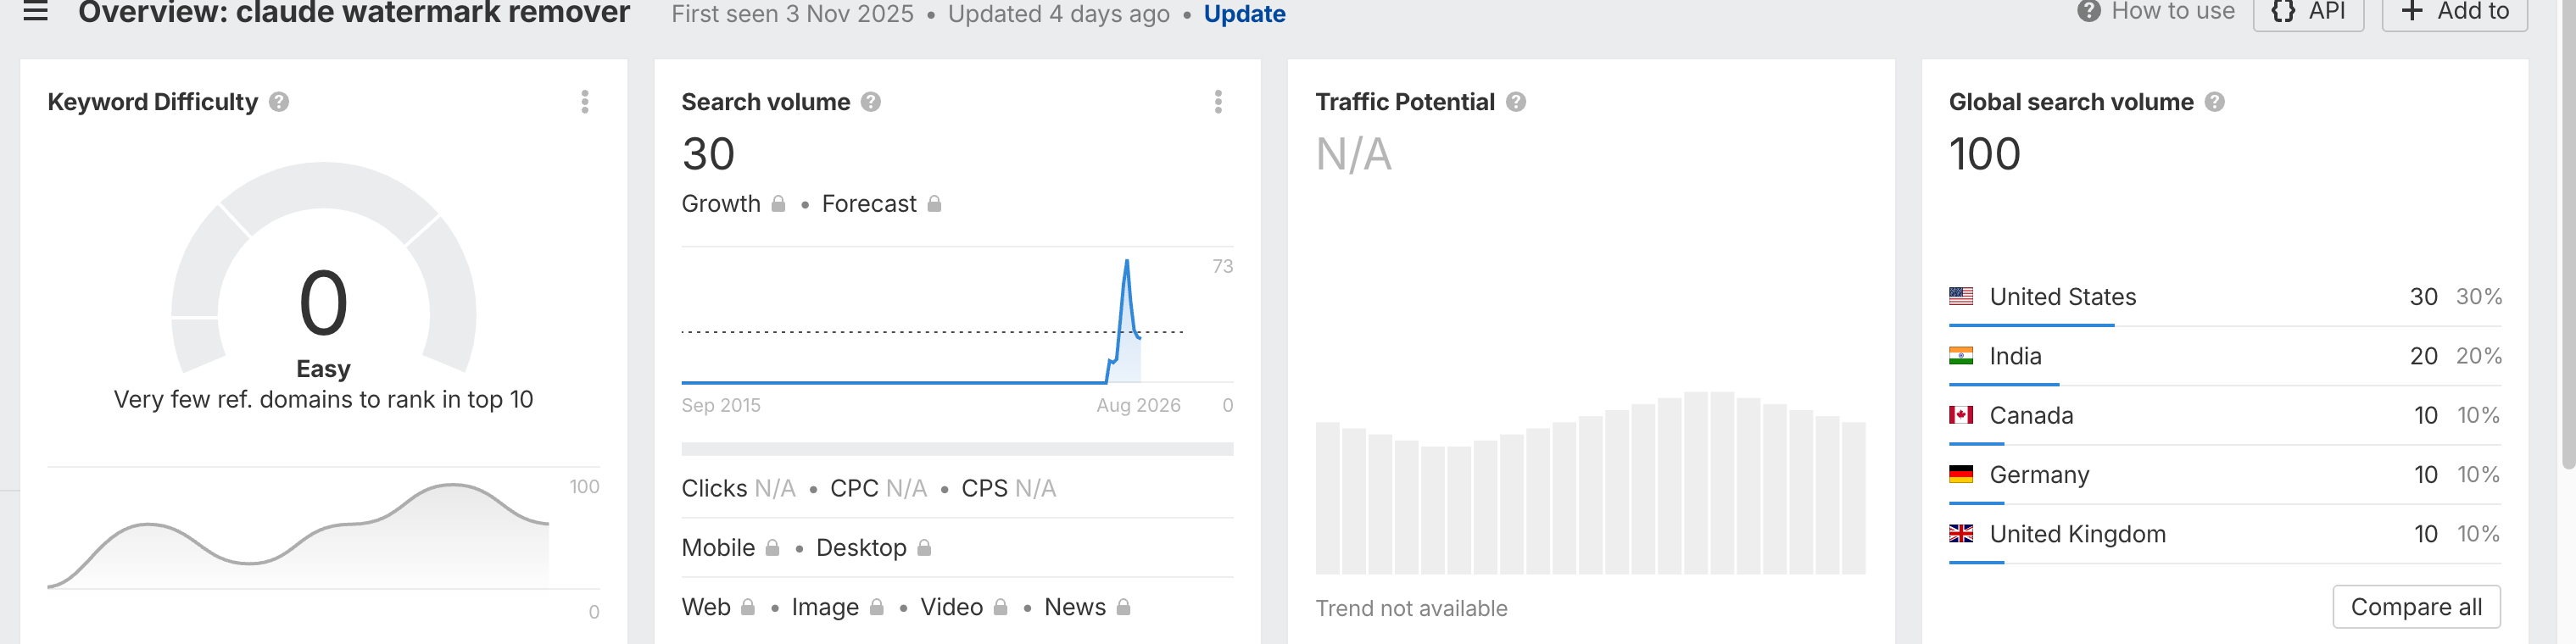
You could generate with one model, rewrite with another, edit manually, combine outputs, regenerate individual sections, or route pieces of text through different models.
OpenRouter, for example, gives developers access to a large selection of models through one interface. So it isn’t difficult to imagine software that generates with one model and rewrites with another, or even chooses a different model for different sections.
That doesn’t prove the watermark will disappear.
It does show why watermarking becomes much harder once you’re dealing with people who actively don’t want the mark to survive.
There’s another problem.
For Google, publishers, universities, or anyone else to detect a watermark, they need some way to recognize or verify it.
And once detection becomes widely available, people trying to evade it can test against it too.
Generate.
Check.
Rewrite.
Check again.
Repeat until the signal is weak enough or gone.
We’ve already watched this happen with AI detectors and the entire “humanizer” industry built around them. There is no reason to assume watermark detection would exist in a completely separate economic reality.
This is also why I wouldn’t look at Claude’s watermark and conclude that programmatic SEO suddenly disappears.
The people producing low-effort pages at scale are exactly the people most likely to automate around a new constraint.
Google’s own guidance gives us a better way to think about this anyway. Google says using generative AI is not inherently against its guidelines. The problem is generating large numbers of pages without adding value, particularly when the purpose is manipulating search rankings.
That distinction matters.
If someone uses Claude to build a useful calculator, tool, estimator, quiz, or interactive resource that genuinely helps visitors, the fact that Claude helped write the code is not automatically the problem.
In fact, this may push some SEO people in a more useful direction.
Instead of producing another thousand interchangeable articles, use these models to build things.
A mortgage calculator.
A calorie estimator.
A position-size calculator.
A study planner.
A pricing tool.
A comparison tool.
A diagnostic quiz.
Something a person can actually use.
Google’s current Search guidance explicitly emphasizes unique, useful, non-commodity content and warns against producing many pages simply to cover every possible query variation.
That seems like a much more interesting response to this whole situation than spending the next five years trying to make one AI system fool another.
The watermark may change the workflow.
It probably won’t end the workflow.
Note: This piece is my interpretation of what’s happening, shaped by my experience writing long-form content and by some research into how people are responding to Claude’s latest move toward watermarking text. During this process, I used several AI detection tools and made some observations of my own.
Author: Hawrry Bhattarai
Important:
Reproducing this without permission isn’t okay. If it was useful, share the link, that’s how good work travels. This isn’t generic commentary. It comes from actual experience.
Good point about the difference between AI detection and actual authorship. Detector scores aren’t always definitive, especially with heavily edited or AI-assisted writing. An Undetectable AI Humanizer can help make drafts feel more natural, but human editing and judgment still matter most.
Same... They’re total garbage.🩷🦩